stonebrigade@stonebrigade

conPACT is a Claude Code mod that automatically compacts a session's context after a task finishes via an MCP tool, and prompts to compact idle sessions before the prompt cache expires. It ships as an in-process plugin hooks mod in Claude Code 2.1.284+, with a Stop hook fallback over Remote Control, and also supports Codex/ChatGPT Desktop. Author reports ~4.7% spend savings and lower peak context, MIT licensed.
The author describes conPACT, which queues self-compaction through an MCP tool (queue_compaction) so compaction runs as a real /compact after the final answer, preserving chat history while summarizing live context. It supports a focus instruction and minimum size, and shows a toast five minutes before cache expiry offering immediate or per-session auto-compaction, with a status row above the prompt. Built with Claude Code and used on its own dev sessions since mid-September, it integrates as a mod using the new in-process plugin hooks in Claude Code 2.1.284+, or via a Stop hook sending /compact over Remote Control. It also works for ChatGPT Desktop (Codex) via an optional sidecar and Codex CLI via a Stop hook. Key learnings: /compact cannot be sent mid-turn, so compaction happens after the turn ends and at most once; timing matters more than size. Metrics over 187,978 API calls show 134 conPACT compactions all on warm cache versus 30 of 121 manual ones warm, roughly $5.67 vs $0.20 per compaction at list price, median peak context down from 501k to 337k tokens, median cold-resume re-read down from 493k to 255k tokens, and cold-resume share of spend down from 6.4% to 3.8%, with no rework penalty. Requires Python 3.11+, standard library only, runs on Windows/Linux/macOS, MIT licensed. GitHub: https://github.com/st0nebridge/conPACT
See the original source for installation instructions.
Long Claude Code sessions cost you twice. The context keeps growing after the work that needed it is done, and if you come back after the prompt cache has expired, your next message re-reads all of it uncached. /compact fixes both, but only if you type it at the right moment. I usually didn't. What it does When a piece of work is finished, Claude queues a compaction of its own session through an MCP tool ( queue_compaction ). It runs after the final answer, as a real /compact : your chat history stays visible and only the live context is summarised. It can take a focus ("keep the plan and the open decisions") and a minimum size. When a big session sits idle, a toast appears five minutes before the cache expires and offers to compact it now, or always for that session. A row above the prompt follows the request: queued, compacting, then what it came to. How Claude Code was used I built it with Claude Code, and it has been compacting its own development sessions since mid-September. In Claude Code 2.1.284+ it ships as a mod (the new in-process plugin hooks), so the session compacts itself and draws the row above the prompt. Without the mod, a Stop hook sends /compact over Remote Control. It also works for ChatGPT Desktop (Codex) through an optional sidecar, and for the Codex CLI through a Stop hook. What I learned You can't send /compact mid-turn. A busy session receives it as plain text and it never runs. So the tool only records the request, and the compaction happens after the turn ends: always after the final answer, and at most once. When you compact matters more than how small. I measured it over 187,978 of my own API calls (12 days with conPACT, 80 before). All 134 conPACT compactions ran on a warm cache, against 30 of the 121 I'd typed by hand. A cold compaction re-reads the whole context at the cache-write price first, so that's roughly $5.67 against $0.20 per compaction at list price. Median peak context per session fell from 501k to 337k. The idle toast does its job: a cold restart now starts from a compacted context. The median re-read on a cold resume fell from 493k to 255k tokens, and cold resumes' share of spend fell from 6.4% to 3.8%. No rework penalty. Claude re-reads some files after a compaction, but the next prompt was a correction 5.5% of the time, against 6.1% in ordinary turns. Net: about 4.7% of spend saved at list price (1.8–13%, depending on what you assume I'd have done otherwise). It's modest, and the "after" period is only 12 active days, but every compaction saves more than it costs. Python 3.11+, standard library only. Windows, Linux and macOS (the test suite runs on all three; most of my live use is on Windows). MIT licensed. GitHub: https://github.com/st0nebridge/conPACT Feedback welcome, especially from anyone on macOS or Linux. submitted by /u/stonebrigade [link] [comments]

Claude Code plugin that compresses tool output, checkpoints before compaction, scores context quality, and reports token/cost savings on a local dashboard; ships hooks and a localhost daemon.
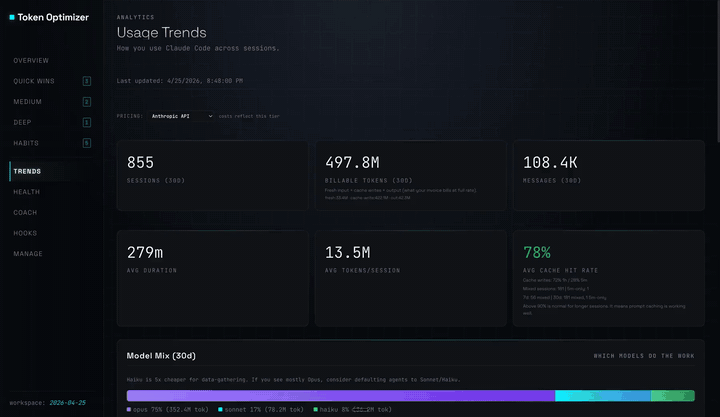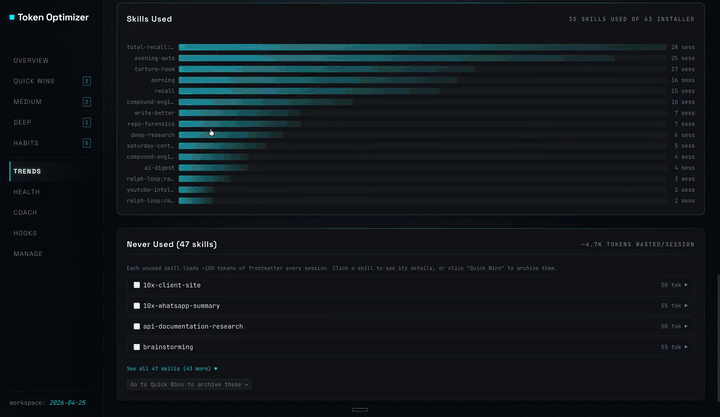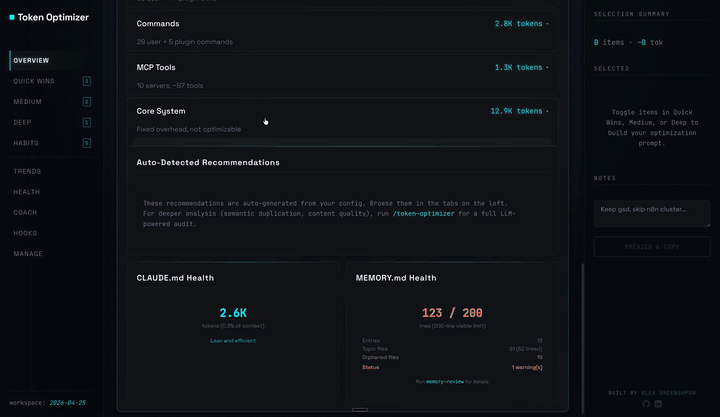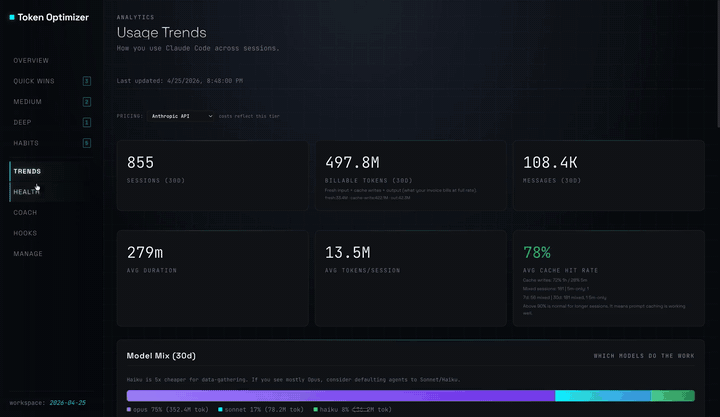

A Claude Code mod that keeps an idle session's prompt cache warm with silent pings, then compacts large sessions once while the cache is still warm.
A Claude Code mod that keeps the one-hour prompt cache warm during breaks and stops a cold send once with its estimated rewrite cost. Warming uses model requests and costs tokens. Requires Claude Code 2.1.287+.