
josippapez@josippapez
josippapez/ai-setup/tree/main/claude/plugins/verified
一个 Claude Code 插件,提供 Stop/SubagentStop hook,阻止回答声称会话从未检查过的事情,并配有重放模拟器和用于发布前评分声明模式变化的工具。
josippapez/ai-setup/tree/main/claude/plugins/verified
Verified 是一个 Claude Code 插件。它的 Stop 和 SubagentStop hooks 会根据会话中实际运行过的内容评估回答中的事实声明——路径声明检查文件是否存在和工具输出,结果声明检查干净的 test/build/lint 运行,URL 声明检查已抓取的 URL。没有依据的声明会把这一轮送回模型;猜测仍然合法,被引用的片段算作提及;阻止 3 次后,hook 会降级为把声明标记为未验证。判定结果会记录到 ~/.claude/verified/ 下的重放账本,因此可以基于固定的真实会话历史离线评估候选配置变更(V = catches − false positives − 0.25 × blocked turns),遵循 Dream-RSI 的无回归方法。一个 ui.tsx 组件会显示 toast,并在提示框上方显示列出被标记声明的横条。README 记录了启用和停用的声明类别、可选的 LLM judge、带测量比例的放弃方案,以及可通过 node --test 运行的测试。
请先查看作者 README 确认 marketplace 和插件名称;命令可能随仓库结构改变。
claude plugin marketplace add josippapez/ai-setup
claude plugin install verified
A Stop hook that blocks an answer when it claims something the session never checked. The dev-core rules already say "no claim without a file:line, a command output, or a fetched URL". This plugin is the part that enforces it. Before it existed, every correctness mechanism in the repo was advice given before the model acted, and nothing looked at the answer.
It exists for two failures the user reported: answers asserting things nobody checked, and steps skipped mid-task (a "tests pass" with no test run).
The hook reads the session transcript, builds a list of what actually ran, and matches the answer against it. Each claim class is on or off in CONFIG in hooks/claim-patterns.cjs.
| Class | Fires on | Backed by | State |
|---|---|---|---|
| path-missing | a file path | a tool having printed the file's name this session, or the file existing on this machine: from cwd, the git root, the tracked-file list, or the repo of any folder the answer names by ~/ or / path | on |
| command-outcome | "tests pass", "build succeeds", "it works" | a clean test/build/lint run after the last file write | on |
| url | a cited URL | a tool having printed that URL, WebFetch or WebSearch of that host, or an agent-browser, curl or wget command naming it | on |
| path | a file path | a Read/Edit/codegraph of it | off |
| version | v1.2, 1.2.3, "version 4" | find_libs, a manifest read, opensrc | off |
| absence | "there is no X" | a Grep/Glob/rg/codegraph search | off |
Guesses stay legal. The gate checks labelling, not certainty: "I'd use Postgres" passes, and "Postgres handles this natively" blocks unless something was fetched. A span in "double quotes" or after "e.g." counts as a mention, not a claim. A path-missing block asks the model to correct the path, not delete it. After 3 blocks on the same claims, the hook stops blocking and tells the model to mark them unverified.
SubagentStop runs the same checks on subagent answers, against the subagent's own transcript.
~/.claude/verified/, deliberately outside the plugin data dir so a reinstall never wipes it. It holds ledger.jsonl (one node per evaluated turn, with answer text, so it never goes in git), manifests/, worlds.lock.json (the pinned replay history), replay-log.jsonl and offsets.json.
Any change to what gets flagged is scored before it ships. /verified-replay replays a candidate config over the pinned history of real sessions, with no model calls and nothing re-run:
node hooks/replay.cjs --corpus            # current config on the pinned history
node hooks/replay.cjs --corpus --sweep    # every single-knob candidate
node hooks/replay.cjs --candidate <file>  # a forked claim-patterns.cjs vs current
The score is V = catches − false positives − 0.25 × blocked turns (hooks/replay.cjs:91). A change ships only if V doesn't drop. This follows Dream-RSI (dream-rsi.com): the recorded history works as an exact simulator, the scorer (hooks/labels.cjs) stays fixed, and the current config is always one of the candidates. Don't tune labels.cjs to make a favoured config win. Change it only when you've looked at a labelled flag and shown it wrong.
Scores per commit, the scorer's blind spots and the gap to the best possible score are in RESULTS.md.
A fix that only removes wrong blocks can lower V, because the labeller credited those blocks as catches:
On 2026-09-30 the user overrode the rule for three fixes whose removed blocks were all wrong:
| Fix | V with fix vs before |
|---|---|
| Bash agent-browser/curl/wget URLs count as fetched | 371.6 vs 398.1 |
| $param and (group) route folders stay part of a path | 369.8 vs 371.6 |
| A relative path is also looked up in the repos the answer names | 369.3 vs 369.8 |
Overriding again needs the same evidence: every block the fix removes has to be a wrong block. Fixing the labeller so it can see these cases would end the need for overrides.
judge/, off unless VERIFIED_JUDGE_ENABLED=1. Replayed over 476 real turns it fired on 92.5% of them, and each call took 5 to 56 seconds (median about 38) with one call in five failing. The time goes to claude -p starting up, not to the model, so a smaller payload doesn't help. Cost was never the issue at about $0.0017 per turn. Haiku 4.5 got 5 out of 5 on the classification probe, so quality wasn't the problem either.claude -p --bare for the judge. It skips hooks and plugins, but it also breaks login, and the child exits with "Not logged in". The judge uses --settings judge/judge-settings.json plus --strict-mcp-config instead, and VERIFIED_JUDGE=1 stops the child's own Stop hook from recursing.path (was the file read this session). It caught 48 claims over 3260 turns, while blocking 202 the session had already printed. The existence check does the job without those false positives.version. It produced 2 catches out of 67 unresolved flags over 651 turns, the worst ratio of any class. Matching version digits can't tell whether a claim about a release is true.absence. It produced 66 flags over 3260 turns, and no signal ever confirmed one either way.path alongside path-missing. It adds 73 catches but also 179 blocked turns, which scores worse at the 0.25 block weight.command-outcome to a note. It would lose the only class with zero false positives.node hooks/replay.cjs), not only the old-transcript corpus. Since 2026-09-30 a path block there counts as a catch only if the rewrite kept the file.url become a non-blocking note? That would cut the block rate from 18.3% to 16.2%.node --test claude/plugins/verified/hooks/verify-stop.test.cjs
hooks/ui.tsx shows a toast and a band above the prompt listing the flagged claims whenever the Stop hook sends an answer back, since the block reason otherwise reaches only the model. The band clears on the next prompt or on Dismiss.

了解缓存的 /loop worker 和 CronCreate 后台自动化。ruflo 系列每项周期任务都使用的基础插件。

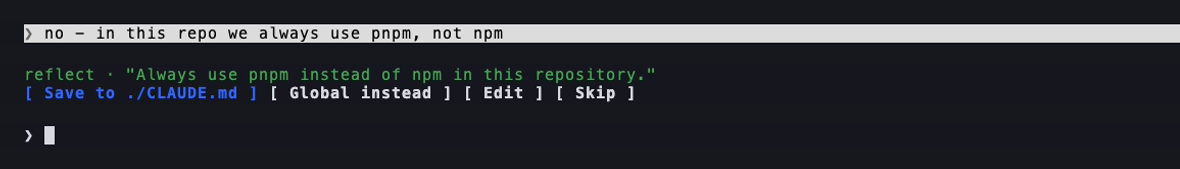
作为 Claude Code mod 的 claude-reflect:每个简短提示都会进行模型检查,找出可复用的修正(支持任何语言);提示符上方的横条让你按一次就将它们保存到 CLAUDE.md。

Claude Code 内的早期 crit:在面板中评论对话、差异或文件,把审查发送给 Claude,并在线程中阅读 Claude 的回复。