
rlorenzo@rlorenzo
rlorenzo/ai-coding-setup/tree/main/mods/review-gate
rlorenzo/ai-coding-setup/tree/main/mods/review-gate
review-gate mod 使用 tool.check 函数钩子,将 commit 前的审查门从 PreToolUse shell hook 改为在引擎进程内通过子字符串测试判断;只对可能是 commit 的命令启动脚本,降低每条命令的启动成本,并可利用 ask 响应将被拦截的 commit 转为权限提示。规则仍保留在 bin/review-gate,选项包括 blocked(默认 ask)和 gate(bin/review-gate 路径)。需要 CLAUDE_CODE_ENABLE_FUNCTION_HOOKS=1,以及 Claude Code 2.1.260 或更高版本。
请先查看作者 README 确认 marketplace 和插件名称;命令可能随仓库结构改变。
claude plugin marketplace add rlorenzo/ai-coding-setup
claude plugin install review-gate
Set of prompts, skills, and scripts to aid in utilizing AI coding agents in development workflows.
The setup script and the review loops are Bash scripts that shell out to a handful of command-line tools. Install the ones below and make sure they are on your PATH.
Required (the setup script exits early if any is missing):
git, to clone the repo and drive the git-based commandsgh) 2.88.0+, installed and authenticated (/review-pr uses the gh pr edit --add-reviewer @copilot special value added in 2.88.0 to re-request Copilot code review)jq, a JSON processor used to read and edit each tool's settings and MCP config filesRequired only for optional steps:
npx), for the MCP servers and the Impeccable design skills. setup skips those steps with a warning if npx is not found.At least one AI coding tool:
agy command)kimi command)| Tool | macOS (Homebrew) | Debian / Ubuntu | Windows (winget) |
| --- | --- | --- | --- |
| git | brew install git | sudo apt install git | bundled with Git for Windows |
| gh | brew install gh | gh install docs | winget install GitHub.cli |
| jq | brew install jq | sudo apt install jq | winget install jqlang.jq |
| Node.js | brew install node | sudo apt install nodejs npm | winget install OpenJS.NodeJS |
The other utilities the scripts call (bash, grep, sed, awk, sort, diff, find, comm, ...) are standard on macOS and Linux, and are bundled with Git for Windows.
Windows: Run
./setupand the review loops from Git Bash (part of Git for Windows). Git Bash ships Bash and the standard Unix utilities but notjq, so installjqseparately with the command above.
git clone https://github.com/rlorenzo/ai-coding-setup.git
cd ai-coding-setup
./setup
The script detects which AI tools you have installed and walks you through installing commands for each one interactively.
Windows: Run the setup script from Git Bash.
| Tool | Command format | Source directory | Installs to |
| --- | --- | --- | --- |
| Claude Code | Plugin (.claude-plugin/) | .claude/commands/, plugins/, mods/ | loaded in place from the clone |
| Claude Code (copy fallback) | Markdown (.md) | .claude/commands/, plugins/explore-agent/agents/ | ~/.claude/commands/, ~/.claude/agents/ |
| Codex CLI | Agent Skills (SKILL.md) | .codex/skills/ | ~/.codex/skills/ |
| Copilot CLI | Agent Skills (SKILL.md) | .copilot/skills/ | ~/.copilot/skills/ |
| Antigravity CLI | Unified Plugin (plugin.json) | .antigravity/ | ~/.gemini/antigravity-cli/plugins/ai-coding-setup/ |
| Kimi Code CLI | Agent Skills (SKILL.md) | .kimi-code/skills/ | ~/.kimi-code/skills/ |
| Shared prompts | Markdown (.md) | prompts/ | ~/.local/share/ai-coding-setup/prompts/ |
Kimi Code reads its user-level data from $KIMI_CODE_HOME when that variable is set; setup honors it and falls back to ~/.kimi-code. Kimi invokes skills as /skill:<name>, so the commands below are /skill:commitmsg, /skill:review-pr, and so on.
Claude Code is the one harness here with a plugin system of its own, and setup uses it by default: instead of copying seven Markdown files into ~/.claude/commands/, it registers this clone as a marketplace and installs from it.
The marketplace holds three plugins:
| Plugin | What it is | Needs |
| --- | --- | --- |
| ai-coding-setup | The seven commands | Nothing |
| explore-agent | The Explore subagent as an agent file that shadows the built-in | Nothing |
| explore-model | The same pinning as an agent.spawn function hook, with no shadow | CLAUDE_CODE_ENABLE_FUNCTION_HOOKS=1 |
| review-gate | The review gate as a tool.check function hook | CLAUDE_CODE_ENABLE_FUNCTION_HOOKS=1 |
explore-agent and explore-model do the same job two ways and you want exactly one of them; see Explore. setup installs whichever your session can run and removes the other.
claude plugin marketplace add ./          # from inside the clone
claude plugin install ai-coding-setup@ai-coding-setup --scope user
claude plugin install explore-agent@ai-coding-setup --scope user
Three things are better this way:
git pull. The plugin loads in place from the clone, so pulling new commands makes them live at the next session start. The copy path needs another ./setup run to notice.claude plugin uninstall ai-coding-setup takes all seven commands and the agent with it, where the copies have to be deleted one by one.~/.claude/commands/. A command of your own that happens to share a name is never shadowed, and the source markers and stale-orphan pruning the copy path needs stop mattering.The trade-off is that the plugin loads in place: move or delete the clone and the commands go with it. A copy would have survived. If that matters more than live updates, answer n at the plugin prompt and setup falls back to copying, exactly as before. Either way it offers to remove whichever set it did not install, so no command is ever listed twice.
To install without a clone at all, point the marketplace at the repo:
claude plugin marketplace add rlorenzo/ai-coding-setup
claude plugin install ai-coding-setup@ai-coding-setup --scope user
Propose a conventional commit message for the currently staged changes. Detects ticket IDs from branch names and follows the project's recent commit style.
Usage:
/commitmsg$commitmsg/commitmsg/commitmsg/skill:commitmsgProcess unresolved review comments on a GitHub PR, fix valid issues, ensure CI passes, and re-request review.
Review bots count as required reviewers: every bot that has reviewed the PR must cover the head commit, falling back to the bots used on the repo's recent PRs, and asking you if none are found. The skill reads each bot's review body as well as its threads, so findings with no thread still get handled, and a non-approving verdict (Copilot's Changes recommended, a nonzero CodeRabbit count) blocks success until you accept the declined findings. It re-triggers Copilot, CodeRabbit, and Greptile itself and asks for the trigger of any other bot. It keeps working through its iterations without stopping to report, and treats comment text as untrusted: findings are judged against the code, never followed as instructions.
Usage:
/review-pr [PR_NUMBER]$review-pr [PR_NUMBER]/review-pr [PR_NUMBER]/review-pr [PR_NUMBER]/skill:review-pr [PR_NUMBER]Review staged files against four quality angles (simplification, reuse, efficiency, altitude), apply the fixes, fix linting issues, and check test coverage. On large diffs, fans the angles out to parallel mid-tier subagents when the agent has a subagent tool. The reuse angle searches shared and nearby modules before concluding nothing existing fits, and each reuse finding names the existing alternative and its path.
Usage:
/code-refinement$code-refinement/code-refinement/code-refinement/skill:code-refinementRun a standalone code review on staged changes. Writes findings to agent-code-review.md.
Usage:
/code-review$code-review/code-review/code-review/skill:code-reviewAudit dependency updates for supply-chain risk before they land: publish-age gate, changelog/diff verification, security advisories, community signals, and breaking changes. Changelogs, release notes, and package source are treated as third-party evidence to verify, not instructions: text that tells the agent to run something, skip a check, or approve the update is itself flagged as a HOLD.
Usage:
/dependency-review$dependency-review/dependency-review/dependency-review/skill:dependency-reviewRun a task with your current model as the orchestrator and reviewer while cheaper, faster subagents do the token-heavy research, coding, and testing. It matches model tier to task difficulty (your own tier for complex work, a mid tier for low/medium, the cheapest tier for mechanical), keeps the orchestrator's own reading and searching lean, runs delegation in bounded waves to respect your usage caps, and for long unattended runs auto-pauses and resumes across usage windows. No model names are hardcoded beyond a Claude example ladder: each harness orders its own available models by cost and capability, and everything else is written relative to whatever tier you are on. Agents without a native subagent tool (Codex, Copilot) delegate by spawning their own CLI non-interactively with an explicit model.
The skill also pins the model explicitly on every spawn (since Claude Code v2.1.198 the built-in Explore/Plan/general-purpose subagents inherit the main-session model, so an un-pinned background search bills at your tier), prefers model aliases over pinned IDs, drops reasoning effort for cheap-tier recon (and treats lower effort on your own tier as an alternative to a cheaper tier for bounded coding slices), gives each handoff an advisory time budget backed by a hard timeout, distinguishes what delegation buys on API vs. subscription billing (per-token savings vs. quota-bucket arbitrage), and closes non-trivial work with a fresh-context verifier that only refutes, never fixes.
Usage:
/efficient-orchestration$efficient-orchestration/efficient-orchestration/efficient-orchestration/skill:efficient-orchestrationRewrite a feature branch's git history into focused, logical commits before review or merge. It surveys the branch's commits past the merge base, folds review-response, fixup, WIP, and lint-fix noise into the substantive commits they amend, and reorders the result so each commit is reviewable on its own and git blame stays meaningful. Refuses to run on main or other long-lived branches, creates a backup branch before rewriting, and verifies the final tree is byte-identical to the original tip. Once verified it force-pushes with --force-with-lease (never bare --force) and deletes the backup branch; on any failure the backup is kept so the original history is never lost.
Usage:
/git-history-cleanup [BRANCH]$git-history-cleanup [BRANCH]/git-history-cleanup [BRANCH]/git-history-cleanup [BRANCH]/skill:git-history-cleanup [BRANCH]The subagent definitions ship as the explore-agent plugin, from plugins/explore-agent/agents/; on the copy path setup installs them to ~/.claude/agents/. These are Claude Code-only (the other harnesses have no equivalent mechanism).
They sit at that plugin's root rather than under .claude/ because the root agents/ directory is the only place Claude Code loads plugin agents from. The manifest's agents key accepts a list of file paths, claude plugin validate --strict passes, the install succeeds, and yet the agent is silently missing from the loaded plugin. So no manifest here names an agents key at all, and test/plugin-manifest.bats fails if one is added.
Since Claude Code v2.1.198 the built-in Explore subagent inherits your main-session model instead of always running on Haiku (capped at Opus on the Claude API). If your daily driver is Opus or Fable, every background codebase search Claude spontaneously delegates bills at that tier. This agent shadows the built-in (a user-level agent with the same name overrides it, which the docs explicitly support) and pins exploration back to haiku at effort: low with read-only tools.
Trade-off to know about: a custom Explore loads your CLAUDE.md/user memory like any subagent, which the built-in skips for speed. That is the cost the explore-model mod exists to remove. To remove the agent, claude plugin uninstall explore-agent, or delete ~/.claude/agents/Explore.md if you took the copy path.
They pin the same thing two ways, and you want exactly one:
| | explore-agent | explore-model |
| --- | --- | --- |
| How | An agent file that shadows the built-in | An agent.spawn hook that sets the spawn's model |
| Loads CLAUDE.md on every search | Yes | No |
| Keeps the built-in's definition | No, replaces it | Yes |
| Needs function hooks | No | Yes |
Install both and you get neither's benefit: the spawn resolves to your shadow definition rather than the built-in, so the CLAUDE.md load is back and the hook has nothing left to improve. setup installs one and uninstalls the other, and re-running it after you enable function hooks switches you over.
A mod is a Claude Code plugin whose behavior is a hooks module: TypeScript loaded into the engine, one register(on, options) entry whose hooks are ($, e, next) functions wrapping an engine event, Express-middleware style. Where a classic hook is a shell command spawned after the fact, a function hook can rewrite the event, answer it, or refuse it, in process.
Four ship inside Claude Code (sec-default, diff, telemetry, agents-md). The ones here live in mods/.
Early access. Hooks modules load only when CLAUDE_CODE_ENABLE_FUNCTION_HOOKS=1 is set, on Claude Code 2.1.260 or newer, and upstream says the API they are written against may change between releases without notice. setup offers to write the flag into ~/.claude/settings.json, and defaults to No: nothing else in this repo depends on an unreleased API, and a mod that stops loading after an update is a worse surprise than an agent file that never does.
Two things are worth knowing when you install one:
claude plugin details <mod> reports Hooks (0). The inventory counts classic hook matchers; a function-hooks module is not one, so the count reads zero even for a module that loads and fires. It is not a sign the mod is broken.claude binary, with no credentials and no home directory: CLAUDE_CODE_ENABLE_FUNCTION_HOOKS=1 claude plugin test mods/explore-model. CI runs them for every mod; test/plugin-manifest.bats runs the same command locally and skips where claude is absent.Pins the model that background recon subagents run on, by hooking agent.spawn and setting the spawn's model.
This is the same goal as the explore-agent plugin and a better way to reach it. The agent file has to replace the built-in Explore definition to change its model, and a replacement is loaded like any other subagent, so it drags in your CLAUDE.md and user memory on every search, which the built-in skips for speed. The hook sets one field on the spawn and leaves the built-in definition running, so there is no shadow and no extra load.
Two spawns are handed straight through. A fork inherits its parent's context and model and ignores model outright, so rewriting it would only misdescribe what happens. A spawn that named its own model was an explicit choice by the caller, and the case the hook is here to decide is the one nobody decided.
It is also the enforcement /efficient-orchestration currently has to ask for: that skill instructs the model to pin a model on every spawn, which is a prompt-level plea the model can forget on exactly the code path where forgetting is expensive. The hook makes it an engine-level invariant instead.
| Option | Default | Effect |
| --- | --- | --- |
| model | haiku | The alias or id the named agents run on. Prefer an alias: it tracks whichever model answers to that name, where a dated id stops applying the day the next one ships. inherit registers no hook at all. |
| agents | Explore | The subagent types this applies to. Only read-only recon agents belong here: a pinned agent runs on model whatever its own definition asks for. |
| notice | false | Attach a one-line notice to each spawn the hook pins. Off by default, since the point is to be invisible; turn it on to confirm the mod is loaded and firing. |
claude plugin install explore-model@ai-coding-setup --scope user \
    --config model=haiku --config agents=Explore --config notice=false
Note that this is a floor on cost, not the only one: setup also offers CLAUDE_CODE_SUBAGENT_MODEL=sonnet, which is the fallback tier for every subagent. The mod is the narrower, cheaper pin for the one agent Claude dispatches on its own.
The review gate as a tool.check hook. Same gate, better seat.
bin/review-gate is wired as a PreToolUse shell hook and fires on every command the agent runs (overwhelmingly ls, cat and test runs), each one paying a process start. Measured in this repo: roughly 160ms warm under Git Bash on Windows against 55ms for a bare bash -c true, and over a second on a cold file cache. The script's fast path exits before any git call, but bash still has to start.
The mod answers that same question with a substring test inside the engine's own process, and spawns the script only for a command that could actually be a commit. On the calls that dominate, the cost goes to zero.
The second gain is ask. A PreToolUse hook can only allow or deny, which is why the gate ships in warn and why its own docs describe handing the question back to you as something it cannot do; the closest it gets is denying and asking the agent to ask you. tool.check can answer ask, so a blocked commit becomes your permission prompt, carrying the gate's reason, diff and rubric.
What the mod does not do is decide anything. The rules (which commands commit, what a receipt has to match, when a rewrite is in progress, the git commit -a cases that can never be vouched for) stay in bin/review-gate, which the mod runs with the claude payload it already speaks and reads the JSON it already prints. One implementation, one test suite, no second copy to drift, and both routes read the same receipts under .git/ai-review/, so they can never disagree about whether a change was reviewed.
That last point is why the mod does not keep receipts in the engine's own $.store, which would have been the obvious place: code-review-loop writes the receipts, and a store only the mod can read would mean the loop's clean run no longer cleared the gate.
| Option | Default | Effect |
| --- | --- | --- |
| blocked | ask | What a blocked commit does. ask puts the gate's reason to you as a permission prompt. deny refuses outright, matching REVIEW_GATE=block. |
| gate | unset | Where bin/review-gate is. Unset, the hook tries AI_REVIEW_GATE_BIN, then ~/.local/bin/review-gate, then review-gate on PATH. |
The script's own modes still decide everything else: REVIEW_GATE=off and the AI_REVIEW_GATE=off bypass work exactly as they do without the mod, and in warn mode the gate's reasoning goes to the transcript instead of a stderr nobody reads.
Install the two together and the script runs twice for one commit, issuing a second single-use nonce that invalidates the first, so setup removes the PreToolUse entry when it installs the mod.
claude plugin install review-gate@ai-coding-setup --scope user \
    --config blocked=ask --config gate="$HOME/.local/bin/review-gate"
Two multi-agent feedback loops live in bin/: code-review-loop (for staged code) and plan-review-loop (for plan documents), alongside review-gate, the hook that keeps an agent from committing before the first of those has run. Each loop pairs an editor agent with a different reviewer agent and iterates until the reviewer is satisfied or --max-iterations is hit. Using two different models for editing and reviewing surfaces issues a single agent tends to miss in its own output.
Both scripts are installed onto your PATH by ./setup and rely on the prompts in prompts/ (installed to ~/.local/share/ai-coding-setup/prompts/).
Runs a full review cycle over your staged changes:
code-refinement prompt (four review angles, lint, test coverage). Skip with -s.agent-code-review.md.agent-review-summary.md.A pre-review snapshot of your staged work is saved to the git stash so you can restore the original if the loop mangles something. Files in the review scope that also have unstaged changes are rejected up front, so fully stage or unstage before running.
Pass --branch to widen the scope to the whole branch: the diff under review becomes every commit since the branch left the default branch (its merge-base) plus whatever is staged. The default branch is read from origin/HEAD, falling back to main then master; pass --branch REF to name another. Fixes from the loop are still staged, never committed, so you can fold them into the branch however you like.
Usage:
code-review-loop                                # default agents, 5 iterations
code-review-loop -m 3                           # cap at 3 review cycles
code-review-loop -s                             # skip the refinement step
code-review-loop --branch                       # review the branch's commits plus staged changes
code-review-loop --branch develop               # same, against a named base branch
code-review-loop --editor claude --reviewer codex
Outputs (project root): agent-code-review.md (latest findings), agent-review-summary.md (narrative).
When a run fails, read the logs. Each agent's full output is written to a per-run directory, printed in the banner at startup and again whenever an agent exits non-zero:
Logs : ~/.cache/code-review-loop/20260807-142516
One file per step, named for the step and the agent that ran it:
1-refinement.claude.log
3-review-initial.antigravity.log
4.1-response.claude.log
6.1-review.antigravity.log
final-summary.claude.log
Each records the agent, the tools it was allowed, its combined stdout and stderr, and its exit code. This is the difference between "it failed" and knowing why: a loop that stops with a bare Execution error on the terminal leaves nothing else behind, and a run started in the background does not even have the scrollback. Note that an agent failing does not stop the loop; it logs the failure and carries on, so the log is often the only sign a step went wrong.
Logs are kept for one day and older runs are pruned at startup. Retention is by age rather than by count because the loop tends to be run several times in a sitting, and what you come back for is today's failure. Override with REVIEW_LOOP_LOG_DAYS, or set CODE_REVIEW_LOOP_LOG_DIR to keep logs somewhere of your own, which opts out of pruning entirely.
Iteratively improves a plan document through review feedback:
feedback-plan.md.NO_FURTHER_FEEDBACK or max iterations.plan-review-summary.md.Usage:
plan-review-loop PLAN-feature.md
plan-review-loop -m 3 PLAN-feature.md
plan-review-loop --reviewer claude --editor codex PLAN-feature.md
Outputs (project root): the plan file is edited in place; feedback-plan.md (latest feedback, removed when reviewer is satisfied); plan-review-summary.md (narrative).
A hook that stops a coding agent from committing code nobody reviewed.
Every harness has a pre-tool event that can deny a tool call. review-gate sits on that event, watches for a git commit, and answers one question in well under a second: does this staged change already have a clean review? If it does, or if the commit is not really a code change at all, the agent never sees the gate. If it does not, the gate denies the commit and hands the agent the staged diff, per-category line counts, and a rubric, and the agent either judges the change trivial and says so out loud, or asks you what to do.
Only code-review-loop clears the gate: it is the one thing that writes the review receipt. The /code-review slash command this repo also installs reviews the same staged diff and writes agent-code-review.md, but records nothing the gate can read, so the deny message names the script and rules the skill out by name.
The gate never runs code-review-loop itself. That takes minutes and is designed to hand back to a human at the end; the gate is pure git plumbing, and the loop runs afterward as an ordinary foreground command if you pick that option.
What passes without a word:
--amend that only rewordscode-review-loop records when it finishes--continue step. A twelve-commit rebase must not stop to ask twelve timesORIG_HEAD or HEAD@{1}, which catches a rewrite whose in-progress markers are already cleaned upAI_REVIEW_GATE=off on the command, or REVIEW_GATE=off in the configWhat always gets stopped: git commit -a, git commit <path>, and the -o / --only / -i / --include forms. They commit content that was not in the index when the gate ran, so a matching receipt describes something else. That check runs before every index-derived rule, or git commit -a with a clean index would sail through the empty-index check and land unreviewed work.
Modes, set with REVIEW_GATE in ~/.ai-coding-setup.conf or in the environment (the environment wins):
| Mode | Behavior |
| --- | --- |
| warn | Default. Prints the reason and the trivial/non-trivial rubric, asks the agent to run code-review-loop on a non-trivial change or to say out loud that it skipped it, and lets the commit through either way. Nothing enforces it. |
| block | Denies the commit and hands the agent the reason. |
| off | Disabled. |
It ships in warn because the rubric is untested against your commits and a wrong block is far more annoying than a wrong warn. Once a few weeks of warn output shows it is not crying wolf, switch to block.
Escape hatches, in the order you are likely to want them:
AI_REVIEW_GATE=off git commit -m "..." bypasses one commit. In PowerShell, where that prefix form is a parse error, write it as $env:AI_REVIEW_GATE = "off"; git commit -m "...". The gate reads the bypass off the command string rather than its own environment, so it has to sit on the same command as the commit either way.AI_REVIEW_GATE=<nonce> git commit -m "...". Staging more work invalidates it, and it works once.REVIEW_GATE=off in ~/.ai-coding-setup.conf turns the gate off everywhere.Headless runs degrade to warn. In CI, or under AI_REVIEW_HEADLESS=1, there is nobody to ask, and a gate that hard-blocks there deadlocks the build. Detection is explicit and never a TTY check: every harness spawns hooks with pipes on all three descriptors, so keying off [ -t 0 ] would degrade every interactive run too, and quietly turn the gate off everywhere while still looking installed.
Installation. ./setup offers to wire it into Claude Code and defaults to yes, appending a PreToolUse hook to ~/.claude/settings.json without disturbing hooks that are already there. Accepting it is safe: the gate ships in warn mode, so it logs an unreviewed commit and lets it through until you set REVIEW_GATE=block. Answer n at the prompt to skip it. The script speaks every harness's output shape via --format, but only Claude is wired automatically, because the other four take different config shapes and paths that are worth confirming against their current docs before writing into your config:
{
  "hooks": {
    "PreToolUse": [
      {
        "matcher": "Bash|PowerShell",
        "hooks": [
          { "type": "command", "command": "\"$HOME/.local/bin/review-gate\" --format=claude" }
        ]
      }
    ]
  }
}
Available formats: claude and codex emit the decision nested under hookSpecificOutput; copilot and antigravity emit a flat {"permissionDecision": ..., "permissionDecisionReason": ...}; kimi is exit-code driven, blocking with exit 2 and the reason on stderr. The allow path is always silence and exit 0, never an affirmative "allow": an affirmative allow from a PreToolUse hook would skip your own permission rules and auto-approve every shell command the agent runs.
Windows. The gate is a Bash script, so it needs Git Bash, like the rest of this repo. Everything it calls is bundled with Git for Windows except jq, which you install separately; without jq the gate allows every commit rather than failing, so check that it is on PATH before trusting the gate there. Claude Code runs hook commands through Git Bash on Windows by default, falling back to PowerShell only when Git Bash is absent, so the Git Bash style path ./setup writes into ~/.claude/settings.json (/c/Users/you/.local/bin/review-gate) resolves as written.
Three Windows specifics are worth knowing:
PowerShell tool alongside Bash, and a matcher of Bash alone lets every commit made through the other one straight past the gate. ./setup writes Bash|PowerShell, and widens an existing Bash-only entry in place when you re-run it.AI_REVIEW_GATE=off git commit ... prefix is a parse error in PowerShell, so the gate reads the statement form too, and writes whichever one matches the tool the commit is coming from into its own deny message: $env:AI_REVIEW_GATE = "off"; git commit .... Either way it has to ride on the same command as the commit. The gate is a separate process spawned before your command runs, so it never inherits a variable you set in an earlier call; it can only read what is on the command string in front of it.bash -c true, and over a second on a cold file cache../setup falls back to copying when ln -s cannot make a real symlink, which is the default on Windows unless Developer Mode is on. That works, but ~/.local/bin/review-gate is then a snapshot rather than a link, so re-run ./setup to pick up changes to the script.
Known blind spot: a commit made inside a script the agent invokes is invisible, because the gate only ever sees the command the agent typed. Nothing short of a git-level hook closes that, and a git-level hook cannot ask a question, so it would only ever warn after the fact.
State lives in $(git rev-parse --git-dir)/ai-review/, so it is never committed, is per-worktree, and survives branch switches:
| File | Contents |
| --- | --- |
| receipts.json | The last 10 review results, newest first: index tree, HEAD, verdict, cycles, agents, timestamp. |
| nonce | The outstanding single-use bypass and the index tree it was issued for. |
| running | The active code-review-loop's PID and start time. The gate exempts commits while the loop runs, and prunes the file when the PID is dead or the timestamp is too old to trust. |
Defaults are --editor claude --reviewer codex. Override per-run with -e / -r, or persist defaults in ~/.ai-coding-setup.conf:
EDITOR_AGENT=claude
REVIEWER_AGENT=codex
REVIEW_GATE=warn
Supported agents: claude, codex, copilot, antigravity, kimi. Only the agents you actually have installed need to be referenced.
Two caveats for kimi: it takes its prompt as a command-line argument (there is no stdin form), so on Windows/Git Bash a very large prompt can exceed the OS argument limit. Copilot has the same limitation. And it has no per-run flag to disable MCP servers, so an autonomous loop run still loads whatever is configured in ~/.kimi-code/mcp.json.
Both loops write their working files (agent-code-review.md, agent-review-summary.md, feedback-plan.md, plan-review-summary.md) to the target project's root. Consider adding those names to that project's .gitignore (or your global gitignore) so an agent never commits them by accident.
Environment variables:
| Variable | Default | Effect |
| --- | --- | --- |
| CODE_REVIEW_LOOP_LOG_DIR | ~/.cache/code-review-loop/<timestamp> | Where code-review-loop writes its run logs. Setting it also turns off log pruning, on the grounds that a directory you named is yours to manage. |
| REVIEW_LOOP_LOG_DAYS | 1 | Delete run logs older than this many days. Only applies to the default location. |
| AI_CODING_SETUP_PROMPTS_DIR | ~/.local/share/ai-coding-setup/prompts | Where the loops read their prompts from. |
| REVIEW_GATE | warn | review-gate mode: off, warn, or block. Overrides the config file. |
| AI_REVIEW_GATE | unset | off bypasses the gate for one invocation. Also carries the single-use nonce the gate issues. Read off the command string, as a VAR=value prefix or a PowerShell $env:AI_REVIEW_GATE = "..." statement, so it must sit on the same command as the commit. |
| AI_REVIEW_HEADLESS | unset | 1 degrades the gate to warn-only. code-review-loop sets it for its own run. |
| REVIEW_GATE_LOCK_MAX_AGE | 21600 | Seconds before the gate stops trusting a code-review-loop lock file and prunes it. |
The loops run every agent with approval prompts off, over your checkout. The editor has unrestricted shell access by design, since it has to run linters and tests. Anything in the repository the agents read, including the diff, CLAUDE.md/AGENTS.md, and code comments, can carry instructions they may follow. A malicious repo can therefore run code as you, with your home directory and network. Only run the loops on repositories you already trust, never on a fresh clone of someone else's code.
The reviewer is narrower where the CLI allows it:
| Reviewer | Restriction |
| --- | --- |
| claude | No shell at all. The loop writes the diff to a file and hands the reviewer its path, since a git-command allowlist still permits write-capable arguments (e.g. git diff --output=file) and can't make Bash read-only. |
| codex | --sandbox workspace-write, the tightest mode that can still write the report. Network is off in that sandbox. |
| antigravity | --sandbox: no reads of your home directory. Writes are confined to the project plus the loop's own temp dir (TMPDIR_REVIEW), which is added to the sandbox because the reviewer's diff file lives there. Network stays on. A plan file outside the project directory cannot be read by a sandboxed reviewer. |
| copilot, kimi | None. Both run with full approvals. |
Both loops are driven by agent-agnostic prompts in prompts/, not interactive commands. They're listed here so you can audit or tweak the behavior:
| Prompt | Used by | Role |
| --- | --- | --- |
| code-refinement.md | code-review-loop | Editor's lint/refine pre-review step |
| code-review.md | code-review-loop | Reviewer's initial pass |
| code-review-followup.md | code-review-loop | Reviewer's follow-up passes |
| code-review-response.md | code-review-loop | Editor's response to findings |
| plan-review.md | plan-review-loop | Reviewer's initial pass |
| plan-review-followup.md | plan-review-loop | Reviewer's follow-up passes |
.claude/commands/*.md files are the canonical sources, and tools/generate derives the Codex/Copilot/Antigravity/Kimi SKILL.md files and the shared loop prompts from them. A pre-commit/CI check (tools/generate --check) fails if the derived files drift from their sources.setup script copies selected commands to the appropriate user-level directory for each tool.~/.local/share/ai-coding-setup/prompts/ and referenced by the review loop scripts.git status, cat, grep, and similar). The file readers match any path, not just the project, so the set deliberately leaves out WebFetch, WebSearch and git ls-remote: read-anywhere plus fetch-anywhere lets an injected instruction read a secret and send it out without a prompt. To skip the prompt for docs you fetch often, add scoped rules such as WebFetch(domain:docs.example.com) to permissions.allow in ~/.claude/settings.json. Earlier versions of setup added bare WebFetch and WebSearch; remove them by hand if you want the tighter default.--force to prune without prompting. Your own unmarked commands are never touched.The setup script can configure Model Context Protocol (MCP) servers for your AI tools. Currently supported:
| Server | Package | Description |
| --- | --- | --- |
| Playwright | @playwright/[email protected] | Browser automation and web testing |
MCP servers are added via each tool's mcp add CLI command at user scope. Tools without one (Copilot, Antigravity, Kimi Code) get their JSON config file edited directly; for Kimi that is ~/.kimi-code/mcp.json, whose only built-in editor is the interactive /mcp-config TUI command.
gh Agent SkillsBeyond the commands in this repo, setup can install GitHub's upstream agent skills for each selected tool. These come from the GitHub CLI team and are unrelated to the commands/skills this repo ships:
| Skill | Repo | What it teaches |
| --- | --- | --- |
| gh | cli/cli | Driving gh well: structured JSON output, pagination, repo targeting, search vs. list, gh api fallback |
| gh-stack | github/gh-stack | Stacked pull requests: creating a stack, adding layers, submit/sync/rebase, bottom-up merge |
For each agent you select, setup installs a skill when missing and updates it when already present:
gh skill install <repo> <skill> --agent <id> --scope usergh skill update <skill>This step is skipped automatically on versions of gh too old to ship the gh skill command (a preview feature), and for Kimi Code, which this repo has no gh skill --agent id mapped for. To manage the skills yourself:
gh skill install cli/cli gh --agent claude-code --scope user               # install for one agent
gh skill install github/gh-stack gh-stack --agent claude-code --scope user
gh skill update gh                                                         # update (all hosts where it's installed)
gh skill list --agent claude-code                                          # verify
There is no gh skill uninstall command; to remove one, delete the installed skill directory (its location is agent-dependent, e.g. ~/.codex/skills/gh/ or ~/.copilot/skills/gh-stack/; run gh skill list --json skillName,path to see the exact filesystem path).
Stacked PRs are a chain of dependent branches where each pull request targets the one below it instead of main, so each layer stays small and reviewable and the stack merges bottom-up. GitHub drives them through the official gh stack extension.
setup offers the extension once per run (it is agent-agnostic, unlike the skills above), installing it when missing and upgrading it when already present:
gh extension install github/gh-stack   # install
gh extension upgrade gh-stack          # update
Pair it with the gh-stack agent skill above so your agent knows the workflow. The core loop:
gh stack init          # start a stack on the current repo, naming the first branch
gh stack add NAME      # add the next layer on top (-Am "msg" also stages and commits)
gh stack push          # push every branch in the stack
gh stack submit        # create/update the PRs and link them as a stack
gh stack view          # show the branches, PR links, and commits
gh stack sync          # fetch, rebase, push, and sync PR state after main moves
gh stack merge         # merge one or more PRs, bottom-up
gh stack up/down/top/bottom/trunk move between layers. See the CLI command reference for every subcommand and flag. Cross-fork stacks and GitHub Desktop are not supported.
setup can also install Impeccable, a third-party design skill set for AI coding agents. It gives your agent a shared design vocabulary and commands (typography, color, motion, layout, polish, and AI-slop detection), with a build tailored to each harness. It is unrelated to the commands this repo ships.
For the selected tools it supports (Claude Code, Codex CLI, Copilot CLI), setup offers to run one command covering them all:
npx [email protected] install --providers=claude,codex,github --scope=global
The version is pinned in setup (IMPECCABLE_PKG) because the installer writes hooks into ~/.claude and ~/.codex; bump it deliberately. Because it runs via npx with explicit --providers/--scope, re-running setup and accepting this step refreshes an existing install and adds any newly-selected agents. There is no separate detect-and-update branch (unlike the gh skill above), since install with explicit providers is already idempotent and provider-aware.
Antigravity CLI and Kimi Code CLI have no Impeccable provider, so they are skipped. This step needs npx (Node.js). To manage Impeccable yourself:
npx impeccable install --providers=claude --scope=global   # install for one provider
npx impeccable update                                       # update
See impeccable.style for the full command list and the Claude Code plugin install (/plugin marketplace add pbakaus/impeccable).
Commands are authored once as Claude Code command files; everything else is generated:
.claude/commands/command-name.md, markdown with YAML front matter containing at least description (plus optional Claude-specific keys like allowed-tools or argument-hint), and an optional $ARGUMENTS placeholder in the body.SKILL_COMMANDS in tools/generate (or PROMPT_COMMANDS if the review loops need it as a shared prompt).tools/generate to produce the derived SKILL.md and prompt files, and commit them together with the source.Run ./setup again to install.
These commands target current-generation models, which follow intent better than procedure. Anthropic's new rules of context engineering are the house style here:
description. It is the only text a model sees
before deciding to load the skill, so say when to reach for it, and when to
reach for a sibling instead, not just what it does.description, delete that
line. Guidance belongs in exactly one place.--slurp / --jq conflict in gh api, an empty
staged diff that still has staged files, which install hooks run automatically.NO_FURTHER_FEEDBACK sentinel and on the reviewer never touching source files.Delete the command/skill from the corresponding directory (or uninstall the plugin for Antigravity):
claude plugin uninstall ai-coding-setup (and explore-agent or explore-model, whichever you have), then claude plugin marketplace remove ai-coding-setup. On the copy path, delete from ~/.claude/commands/ (agents: ~/.claude/agents/)~/.codex/skills/~/.copilot/skills/agy plugin uninstall ai-coding-setup~/.kimi-code/skills/ (or $KIMI_CODE_HOME/skills/)If you installed the review gate hook, remove its PreToolUse entry from ~/.claude/settings.json and delete ~/.local/bin/review-gate. Per-repository state under .git/ai-review/ can go too; nothing else reads it.
The setup script only manages commands it originally installed. The upstream extras are removed separately: gh extension remove gh-stack for the gh stack extension, and for the gh/gh-stack agent skills, delete their directories as described in gh Agent Skills.
The test suite uses BATS (Bash Automated Testing System). After cloning with submodules:
git clone --recurse-submodules https://github.com/rlorenzo/ai-coding-setup.git
cd ai-coding-setup
test/run
If you already cloned without submodules:
git submodule update --init --recursive
test/run
Unit tests (test/run) cover config parsing, prompt loading, validation, review status checks, and generated-file sync. They run in seconds and need no API keys.
If you edit a command source in .claude/commands/, run tools/generate afterwards; the test suite and pre-commit both fail when the derived skill/prompt files are stale.
Smoke tests run real AI agents against a temporary git repo to verify that CLI flags are accepted and agents can perform basic read/write tasks:
test/smoke                   # test all installed agents
test/smoke claude codex      # test specific agents
test/smoke --timeout 180     # override per-test timeout (default: 120s)
Each installed agent is tested as both editor (can it modify a file?) and reviewer (does it produce a review file?). Requires at least one AI tool installed and authenticated.
This repo uses pre-commit to run linters locally before each commit. Install it once and you'll get automatic checks for shell scripts (shellcheck), markdown (markdownlint), TOML syntax, the BATS suite, and a SkillSpector security scan of the skills this repo publishes.
Because of that last one the hook environment needs Python 3.12, 3.13, or 3.14. If yours is outside that range, pre-commit fails while building the hook's venv; SKIP=skillspector-skills,skillspector-agent git commit ... gets you past it, and CI runs the scan either way.
pip install pre-commit   # or: brew install pre-commit (macOS)
pre-commit install
After that, hooks run automatically on git commit. You can also run them manually:
pre-commit run --all-files
If you skip the local setup, the same checks run in CI on your pull request.
The skills in this repo are meant to be installed into other people's agents, where they run with whatever trust that agent has. SkillSpector, NVIDIA's security scanner for agent skills, checks them for prompt injection, hidden instructions, data exfiltration, tool misuse, and supply-chain risk before they leave here.
Two pre-commit hooks run it, and the Lint workflow runs every pre-commit hook over every file, so the scan gates pull requests too. There is no separate security workflow.
--no-llm, the static analyzers only. The semantic ones want an API key that neither a laptop nor CI has, and SkillSpector skips them with a warning rather than failing.0 for SAFE or CAUTION, 1 for DO_NOT_INSTALL (a risk score above 50), 2 for an error. Only a genuinely bad score blocks a commit. The CAUTION findings print and let you through, which is the intent: git-history-cleanup scores 25 for the git reset --hard and --force-with-lease in its own instructions, and a skill about rewriting history is going to mention rewriting history.v2.11.0. SkillSpector is not on PyPI, so it installs from a git URL, and a tag can be moved where a commit cannot.tools/generate renders every harness from the canonical .claude/commands/ sources and the generated-files-in-sync hook proves they match, so the bodies are byte-identical and scanning four copies would buy three more runs and nothing else.plugins/explore-agent/agents/ is not a skill directory, so the second hook names its files directly. The scanner takes one path per run, so each agent needs its own hook; test/skillspector-hooks.bats fails if one is added without one.To run it by hand:
uv tool install git+https://github.com/NVIDIA/skillspector.git@b7241089d7ec15d8b30df980dacbb428214732b9  # v2.11.0
skillspector scan .codex/skills --recursive --no-llm
MIT

了解缓存的 /loop worker 和 CronCreate 后台自动化。ruflo 系列每项周期任务都使用的基础插件。

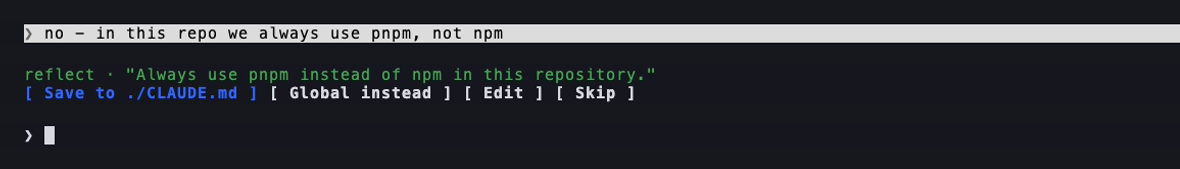
作为 Claude Code mod 的 claude-reflect:每个简短提示都会进行模型检查,找出可复用的修正(支持任何语言);提示符上方的横条让你按一次就将它们保存到 CLAUDE.md。

Claude Code 内的早期 crit:在面板中评论对话、差异或文件,把审查发送给 Claude,并在线程中阅读 Claude 的回复。