
kanetik@kanetik
kanetik/claude-skills/tree/main/skills/later
Claude Code 技能,將離題想法停放在儲存庫外、依儲存庫或使用者層級的儲存區,以一個詞回覆,並透過 SessionStart hook 在之後重播。它屬於 kanetik/claude-skills 外掛集合。
kanetik/claude-skills/tree/main/skills/later
一組小型、單一用途的 Claude Code 技能。/later 會逐字擷取離題想法,不讓目前的工作階段偏離,並按儲存庫或使用者層級儲存(以主要儲存庫根目錄為鍵,因此不會變成差異,也不會隨工作樹消失)。SessionStart hook 會在之後工作階段的頂端重播已停放的項目;完成的工作會與清單核對,將已涵蓋的項目標記為可能已處理並寫明原因,而不是悄悄刪除。可以透過 kanetik-skills 外掛市集安裝,也可以將個別技能建立符號連結或複製到 ~/.claude/skills/。
請先查看作者 README,確認 marketplace 與外掛名稱;指令可能隨儲存庫結構而變動。
claude plugin marketplace add kanetik/claude-skills
claude plugin install later
A collection of Claude Code skills I find useful and worth sharing. It isn't tied to one domain — whatever makes a good, self-contained skill can live here. (Several of the skills so far happen to deal with localization for Android and Play Store content, but that's just where I started, not the theme.)
The skills here are deliberately small and single-purpose. Each one does one job and nothing more: it takes inputs, applies the expert work, and stops. A skill doesn't reach outside its own job — figuring out what to feed it (git ranges, "last PR", "what changed since master") is the conversation's job, and side concerns like committing or opening PRs belong to the caller unless that work is the skill's actual domain (a skill built to run a PR-review loop legitimately drives git and PRs — that's the point of it). Compose the small transforms with whatever commit/PR skills you already use.
| Skill | What it does |
|---|---|
| /translate-strings | Translate Android values/strings.xml keys into every sibling values-{locale}/strings.xml. Preserves placeholders, escapes, plurals, HTML, translatable="false". Always writes locale files alphabetized by key. Supports --add <locale> for onboarding and --retranslate <key> to force a fresh pass. |
| /translate-content | Translate prose — Play Store release notes, app descriptions, FAQs, marketing copy. Reads a per-repo config for output layout, target locales, and char limits. Handles cross-sentence consistency, tone, and whatever char limit the content type carries. |
| /whats-new | Author Play Store "What's New" release notes from your commit log (English only). Pulls commits since the last release tag, drafts bullets within Play's 500-char limit, waits for approval, then writes the source-locale file and hands off to /translate-content for the other locales. |
| /pr-review-loop | Run an iterative PR review loop with a strict role split: reviewers review and post findings to the PR, and this skill is the author — the only thing that touches code. It reads every finding off the PR and decides each one on whether the problem is real and whether it is this PR's work (fix a real problem the change owns, whatever its severity / acknowledge a correct observation that names no problem / reject with a public rationale / file a follow-up issue for genuinely unrelated work), replies, resolves the thread, pushes, and asks for review again, until a round changes no code — nothing blocking outstanding, and nothing fixed that a reviewer hasn't since seen. Reviewers can be bots (Copilot, Codex, anything that posts a review) or /pr-review-skeptic, which it re-runs on every fix push. Bundles config defaults and reference material, reads project overrides from the consuming repo, and degrades gracefully where loop/scheduling primitives are absent. Driving git/PRs is this skill's actual job, not overreach. |
| /pr-review-skeptic | Get an honest second opinion on a PR from reviewers with no stake in it. Blind subagents read the changes at HEAD knowing the project and what the change was asked to do — from the linked issue, your stated intent, or a requirement distilled from the PR description with the author's account stripped out — but nothing of how or why the author built it, judging whether it does the job, treating comments and docs as claims to check against the code, and reporting what is materially wrong rather than what is merely imperfect. A finding is something someone should change — severity then says how bad it is, never whether it counts — and something correct that nobody should have to act on is noted for the record instead, with no thread and nothing owed in reply. Large PRs are partitioned across reviewers plus a pass on how the pieces compose. They are blind to the author, not to the review: the first run reads the whole change cold, and later runs stay as cold on the author's account while being scoped to what has changed since the last review and told which non-blocking consequences the project has already accepted — except the composition reviewer, which is never scoped to the delta and takes the whole change whenever it runs. The review history also reconciles what they found afterwards — a decision that was already weighed stops blocking but stays named in the verdict with the thread that settled it, a defect raised and patched before and still present comes back a severity higher, and a concern that was dismissed once and independently found again comes back flagged with the thread that dismissed it. Every finding gets its own thread, plus a go/no-go verdict: posted when you invoke /pr-review-skeptic or ask for it on the PR, shown in the terminal first for question-shaped asks like "is this ready to merge?". |
| /later | Park a thought that isn't about the work in progress, and get it back when it's useful again. A tangent said out loud drags the session sideways; kept quiet, it's lost. This takes it verbatim, answers in a word, and carries straight on — no clarifying question, no scoping, no offer to do it, because a fragmented session is the cost of responding, not of mentioning. Thoughts go to a per-repository store or, when the idea belongs to some other project entirely, a user-level one. The store lives outside the repo, keyed on the main repository root, so it's never a diff for collaborators and never dies with a worktree when the branch lands. A SessionStart hook replays what's parked at the top of later sessions, and finished work gets reconciled against the list — an item the work happened to cover is marked possibly handled with the reason, never quietly deleted. Storing and returning thoughts is the whole job; doing them is yours. |
| /post-merge-cleanup | Put a repo back to a clean state after a PR lands. Moves the session out of whatever worktree it was in and back to the main checkout, prunes remote-tracking refs, fast-forwards the default branch, and only then removes the worktrees and local branches the merge made stale. Containment is decided by one explicit check against a ref that is current whether or not the checkout cooperated, so the skill can tell a branch whose work is safely contained from one holding commits that exist nowhere else. It refuses to delete anything holding uncommitted work — an untracked file in a worktree exists nowhere else — and asks, with the commits in hand, wherever git genuinely cannot tell a squash-merge from work that never landed. Cleanup only: it doesn't merge the PR, close issues, or tag anything. |
| /ga4-custom-dimension | Register a Google Analytics 4 custom dimension from the command line, so an event parameter Firebase already collects becomes reportable instead of being rejected as "not a valid dimension". Its real job is timing: custom dimensions never backfill, so every event sent before registration reports as (not set) for that dimension permanently — which makes this something to run ahead of the release that starts emitting a parameter, not alongside it. It also knows the two routes that look right and are not, because both cost an afternoon to rediscover: GA4 MCP servers expose only reads, and default application-default credentials carry a scope that does not cover Analytics. The way through is a scoped token minted for a service account without touching ADC. Project identifiers stay in the consuming repo; the skill asks rather than guessing, since a dimension registered against the wrong property can only be archived, never deleted. |
/later runs across all of the others rather than at a point in any of them.
Mid-task, a thought arrives that isn't about the task — "oh, the settings
screen should remember its scroll position" while you're deep in a translation
pass. Say later: settings screen should remember scroll position and it's
written down, acknowledged in a word, and the translation pass carries on
uninterrupted. Nothing gets asked about it, and nothing gets proposed. It shows
up again at the top of a later session in that repo, and if the work happens to
cover it in the meantime, it comes back marked possibly handled with the
reason attached rather than quietly vanishing.
Translating a feature branch's new strings after review settles:
git diff master -- 'app/src/main/res/values/strings.xml', identifies the changed keys, shows them to you/translate-strings with the source path + the explicit key listForgot to translate before merge? "translate the strings from the last PR" — the conversation resolves the PR commit, identifies the diff, calls the skill.
Cutting a release? /whats-new drafts the English release notes from your commits, you approve, then /translate-content propagates to the other locales. If that release starts emitting a new analytics parameter, /ga4-custom-dimension belongs before it ships rather than alongside it: GA4 custom dimensions never backfill, so every event sent before registration reports as (not set) for that dimension permanently — and the first days of a rollout are usually the days you wanted.
Just opened a PR? /pr-review-loop takes it from there. It is one loop with one rule about who does what: the reviewer reviews and never fixes; the loop is the author and the only thing that touches code. Reviewers post their findings to the PR as threads. The loop reads them and decides each one — fix it, acknowledge it without changing anything, reject it with a rationale, or file a follow-up issue for genuinely unrelated work — on three questions that aren't severity: is the problem real (materially wrong, not merely not-quite-right), is it worth acting on (reach, said out loud — who hits this, how often, and what happens to them — with "is this worth another round?" as the organizing question, never "would this block the merge"), and is it this PR's work. A real problem the change owns gets fixed here whatever its severity, because what merges should work. A correct observation that names no problem gets acknowledged and closed — and so does a real one that isn't worth the round a fix would cost, with the reply saying which, because the second is a decision to ship a known defect. Comments, tests and descriptions need to be correct, not perfect, and that second question is where it mostly bites. Only genuinely unrelated work becomes a follow-up issue. Then it replies, resolves the thread, pushes, and asks for review again — until a round changes no code: nothing blocking left, and nothing fixed that a reviewer hasn't since seen. Severity decides what has to be fixed; it never decides what has to be reviewed.
That middle course is what keeps the loop from eating itself. A reviewer with no severity floor is usually correct, and correctness isn't the bar — an adversarial reader can always say something true, especially about prose, which has no failing test to pin it. Without a way to say "you're right, and I'm not changing this," every true remark is either a fix (which owes another review, whose reviewer finds something true about that) or an issue. One of those makes the loop run forever; the other grows a backlog nobody closes. Unlike the translation skills, this one is about git/PR work, so it drives those operations itself rather than leaving them to you.
A reviewer can be a bot (Copilot out of the box) or /pr-review-skeptic, and the pairing is what the loop is built for:
# .github/pr-review-loop.config.yml
reviewers: [skeptic]        # or [copilot, skeptic]
Skeptic's reviewers are blind to the author — they read the code at HEAD knowing the project and what the change was asked to do, but nothing of how or why the author built it, so they judge the code rather than the argument for it, and can say when correct code misses what was asked. When skeptic is a reviewer, /pr-review-loop makes sure the task is on the PR before it starts: a linked issue, or a description that states the problem — and where there's neither, it stops and asks you, and posts your answer to the PR for the reviewers to read. Because it re-runs on every fix push, it also reads the code the fix rounds produced, which is the code with the least review behind it and the most accumulated confidence that it's fine.
They're blind to the author, not to the review. The first run reads the whole change cold. Later runs stay just as cold on the author's account while being told two things the review itself produced: which commit was already reviewed — so the content reviewers read what's changed since, instead of re-deriving round two's findings on round eight — and which consequences the project has already decided about, stated as decisions with none of the reasoning attached. One reviewer is exempt from the narrowing: the composition reviewer takes the whole change, never the delta, because a defect made by two changes written rounds apart appears in neither of their diffs and is visible from nowhere else. That read is expensive, so it happens on the first run and again once the fix rounds stop moving the code — not on every round in between, where it would mostly re-read ground that settled several rounds earlier. Each review records the commit whose whole change was last read, and /pr-review-loop won't call a PR converged until the whole change has been read cold — at HEAD, or on the last of whole_change_taper consecutive clean reads, whose sha the converged summary names. Its history pass then buckets what's left against the PR's own threads, so settled ground comes back marked settled, and a defect a fix round patched and left present comes back a severity higher.
That last part is why the loop replies to every finding and resolves its thread, not just the blocking ones — the reply is the record the next round reads. It's also why rejections are public and specific: a rejection with reasoning settles the finding, and a settled blocking finding still shows up in the verdict with its count and thread, so a bad rejection stays visible instead of quietly disappearing.
Three things to know before turning skeptic on. It needs the skill installed and its five project keys configured (below). It needs allow_agent_posting: true committed to the reviewed repo's .github/pr-review-skeptic.config.yml — an agent-invoked review posts nothing without it, and a reviewer that leaves no trace on the PR can't record decisions, so the loop just re-finds the same things every round. And max_iterations is a backstop worth understanding: the loop terminates on a round that changes no code rather than on silence, so hitting the cap usually means triage went wrong — correct observations read as real problems, each fix owing another review. Reaching it is a reported outcome ("did not converge"), not a quiet stop, and the report carries the evidence: rounds since the last blocking finding, how much of the round was spent on code the loop itself wrote, and the longest repair chain. The loop checks all of the setup at kickoff and tells you what's missing rather than starting a run that can't finish.
Once it merges, /post-merge-cleanup closes the loop the other way: it walks the session back out of the branch's worktree to the main checkout, prunes the refs, fast-forwards the default branch, and then deletes the worktree and the local branch the merge made stale. It reads the merge off git rather than off GitHub, so it needs no gh — but a branch whose remote branch vanished is only evidence, not proof, since a closed-unmerged PR deletes its branch too. What settles it is one explicit question, git log <default>..<branch>: an empty answer means every commit is already in the default branch and nothing is lost. Where that comes back non-empty on a branch whose remote is gone, a squash-merge and work that never landed look identical to git, so it shows you the commits and asks. Every question about a branch is settled before any worktree or branch is removed, so declining leaves both where they were. Anything it can't prove is merged, it reports and leaves, and it never removes a worktree with uncommitted or untracked work in it, at all, under any flag.
You can also run /pr-review-skeptic yourself, on its own, whenever you want a colder read — same skill, posting under your account. If you run it during a loop, the loop recognises the review by its marker and folds it into the current round rather than re-running the reviewers over the same commit.
In Claude Code, add the marketplace, then install from it:
/plugin marketplace add kanetik/claude-skills
/plugin install kanetik-skills@kanetik
This wires the skills in via the .claude-plugin/plugin.json manifest.
Installing copies the skills into Claude Code's plugin cache, so later changes here don't reach you until you ask for them. A plugin updates from your local copy of the marketplace, so refresh that first:
/plugin marketplace update kanetik
Then /plugin manage, pick kanetik-skills, and choose Update now. ("Mark for
update" won't work here — it refuses any plugin whose marketplace entry has a local
source, which this one does.)
If you'd rather keep a local checkout you can hack on:
git clone https://github.com/kanetik/claude-skills.git ~/Projects/claude-skills
Then symlink each skill into your ~/.claude/skills/ directory.
macOS / Linux:
ln -s ~/Projects/claude-skills/skills/translate-strings   ~/.claude/skills/translate-strings
ln -s ~/Projects/claude-skills/skills/translate-content   ~/.claude/skills/translate-content
ln -s ~/Projects/claude-skills/skills/whats-new           ~/.claude/skills/whats-new
ln -s ~/Projects/claude-skills/skills/pr-review-loop      ~/.claude/skills/pr-review-loop
ln -s ~/Projects/claude-skills/skills/pr-review-skeptic   ~/.claude/skills/pr-review-skeptic
ln -s ~/Projects/claude-skills/skills/post-merge-cleanup  ~/.claude/skills/post-merge-cleanup
ln -s ~/Projects/claude-skills/skills/later               ~/.claude/skills/later
ln -s ~/Projects/claude-skills/skills/ga4-custom-dimension ~/.claude/skills/ga4-custom-dimension
Windows (directory junctions, no admin required):
mklink /J "%USERPROFILE%\.claude\skills\translate-strings"  "%USERPROFILE%\Projects\claude-skills\skills\translate-strings"
mklink /J "%USERPROFILE%\.claude\skills\translate-content"  "%USERPROFILE%\Projects\claude-skills\skills\translate-content"
mklink /J "%USERPROFILE%\.claude\skills\whats-new"          "%USERPROFILE%\Projects\claude-skills\skills\whats-new"
mklink /J "%USERPROFILE%\.claude\skills\pr-review-loop"     "%USERPROFILE%\Projects\claude-skills\skills\pr-review-loop"
mklink /J "%USERPROFILE%\.claude\skills\pr-review-skeptic"  "%USERPROFILE%\Projects\claude-skills\skills\pr-review-skeptic"
mklink /J "%USERPROFILE%\.claude\skills\post-merge-cleanup" "%USERPROFILE%\Projects\claude-skills\skills\post-merge-cleanup"
mklink /J "%USERPROFILE%\.claude\skills\later"             "%USERPROFILE%\Projects\claude-skills\skills\later"
mklink /J "%USERPROFILE%\.claude\skills\ga4-custom-dimension" "%USERPROFILE%\Projects\claude-skills\skills\ga4-custom-dimension"
If you don't want the link / want to fork-and-modify locally without syncing back:
cp -r ~/Projects/claude-skills/skills/translate-strings   ~/.claude/skills/
cp -r ~/Projects/claude-skills/skills/translate-content   ~/.claude/skills/
cp -r ~/Projects/claude-skills/skills/whats-new           ~/.claude/skills/
cp -r ~/Projects/claude-skills/skills/pr-review-loop      ~/.claude/skills/
cp -r ~/Projects/claude-skills/skills/pr-review-skeptic   ~/.claude/skills/
cp -r ~/Projects/claude-skills/skills/post-merge-cleanup  ~/.claude/skills/
cp -r ~/Projects/claude-skills/skills/later               ~/.claude/skills/
cp -r ~/Projects/claude-skills/skills/ga4-custom-dimension ~/.claude/skills/
/later needs a SessionStart hook to replay what you park. Option A ships it
declared in the plugin manifest, so there's nothing to do; Options B and C need
it added by hand. It also needs git 2.31 or newer for its per-repository
store. See Per-project setup below.
Installing a subset is fine. The loop ships defaulting to Copilot, so it works on its own; add the skeptic when you want the pairing described above, and the loop will tell you at kickoff if it's configured for skeptic and can't find it.
The skills are project-agnostic — they don't hardcode any paths, brand names, or layouts. To wire a project in:
/translate-stringsNo config needed. The skill operates on standard Android resource layout (app/src/main/res/values/strings.xml and sibling values-{locale}/strings.xml). Project-specific brand names (the things that should not be translated) belong in your project's CLAUDE.md so the conversation can pass them through as guidance.
/whats-newAdd a .claude/whats-new.config.md at your repo root. Keys:
| Key | Required | Purpose |
|---|---|---|
| output_dir | yes | Directory holding the per-locale files (e.g. app/src/main/play/release-notes for gradle-play-publisher, playstore/whatsnew for r0adkll/upload-google-play) |
| file_pattern | yes | Filename template with {locale} — {locale}/default.txt (subdir layout) or whatsnew-{locale} (flat layout) |
| locales | yes | Play Store locale codes; exactly one marked (default), matching the English source |
| since_ref_rule | yes | How to find the previous release, e.g. the last version tag |
| skip_topics | no | Commit topics to omit from the notes (has sensible defaults: analytics, crash logging, A/B tests, refactors, dependency bumps, docs/tests/CI) |
| notes | no | Anything else the skill should know (CI contract, etc.) |
output_dir: app/src/main/play/release-notes
file_pattern: "{locale}/default.txt"
locales:
  - en-US (default)
  - de-DE
  - es-ES
  - fr-FR
  # ... etc
since_ref_rule: "last tag matching ^[0-9]+\\.[0-9]+\\.[0-9]+$"
skip_topics:
  - analytics
  - crash logging
  - A/B tests
The 500-character Play Store limit on release notes is baked into the skill — you don't configure it. It's the release-notes limit specifically; other Play fields have their own, and /whats-new only ever writes release notes. If the config is missing, /whats-new asks for these values and offers to write the file.
/translate-contentAdd a .claude/translate-content.config.md at your repo root. Note the keys differ from /whats-new — this skill uses source_path/output_pattern, not output_dir/file_pattern:
| Key | Required | Purpose |
|---|---|---|
| source_path | yes | Path to the default-locale source file (e.g. app/src/main/play/release-notes/en-US/default.txt, playstore/whatsnew/whatsnew-en-US, docs/faq-en.md) |
| output_pattern | yes | Template for each locale's output, with {locale} substituted |
| locales | yes | Target locale codes; one marked (default), matching the source |
| char_limit | no | Per-locale codepoint limit, for overriding the content type's own or where the type isn't obvious — 500 for Play Store release notes, 4000 for a full description, 80 for a short one, 30 for an app title. Omitting it means "not configured", not "unlimited": /translate-content still applies the limit the content type carries |
| skip_locales_with_content | no | If true (the default), skip locales whose output file already exists with content; set false to always overwrite |
source_path: app/src/main/play/release-notes/en-US/default.txt
output_pattern: app/src/main/play/release-notes/{locale}/default.txt
locales:
  - en-US (default)
  - de-DE
  - es-ES
  - fr-FR
  # ... etc
char_limit: 500
skip_locales_with_content: true
You can also skip the config entirely and drive /translate-content ad-hoc: "translate docs/faq-en.md into de-DE, es-ES, fr-FR, write to docs/faq-{locale}.md, no char limit."
Two. /whats-new and /translate-content read separate config files with non-overlapping keys — /whats-new never reads source_path/output_pattern, and /translate-content never reads since_ref_rule. Keep them as two files. (/translate-content will fall back to reading whats-new.config.md if that's your project's convention, but it only picks up the keys it recognizes, so a dedicated translate-content.config.md is clearer.) When a config is missing, the skill asks for the values and offers to write the file for you.
/pr-review-skepticWorth two minutes: add .github/pr-review-skeptic.config.yml to the repo you review. Run directly, the skill asks on first run without it (drafting answers from your README/CLAUDE.md for you to confirm) and offers to write the file. Run from /pr-review-loop, there's nobody to interview — so the loop checks the config at kickoff and pauses to ask you, rather than reviewing your PR against five invented facts about your project. Committing the file to your default branch settles it for good: the config is read from the PR's base ref, so a committed one covers every run from anywhere.
| Key | Required | Purpose |
|---|---|---|
| project | yes | What the application is, in a sentence |
| users | yes | Who uses it, and roughly how many |
| irreplaceable_data | yes | What can't be recovered if a change destroys it — the key that does the most work, since it turns "data loss" into a named thing the reviewer goes hunting for |
| production_status | yes | Shipping, staged, pre-release, internal — sets what a regression costs |
| architecture | yes | The shape of the system, in two sentences |
| allow_agent_posting | for the loop | true lets a review invoked by another skill or agent post to the PR. Required for /pr-review-loop to use the skeptic as a reviewer — see below |
| priorities | no | Blast-radius order in your own domain's words (has a sensible seven-rung default) |
| files_per_unit | no | Soft target when splitting a large PR across reviewers (default 12) |
| max_reviewers | no | Cap for one PR (default 8); past it, units grow rather than files going unreviewed |
| blocking_severities | no | Which severities hold the verdict (default [CRITICAL, HIGH]). Not which ones post — every finding gets its own thread |
| confirm_before_posting | no | true to preview the review before it's posted, when a person asked for it (default false). On an agent-invoked run there's nobody to preview to, so it reverts that run to posting nothing — which cancels allow_agent_posting. Don't set both |
project: "An offline-first note-taking app for Android."
users: "Consumers on phones and tablets; a few thousand daily."
irreplaceable_data: "User-authored note bodies. Everything else re-syncs from the server."
production_status: "Shipping on Play, staged rollout."
architecture: "Compose UI over a Room database, with a WorkManager sync worker reconciling against a REST backend."

# Only if /pr-review-loop will drive the skeptic in this repo -- see below.
# allow_agent_posting: true
Nothing about any individual change belongs in this file — it describes the project, and it's the only thing the reviewers are allowed to take on faith.
About allow_agent_posting. Leave it out unless you're running /pr-review-loop against this repo. By default a review invoked by another skill or agent posts nothing: it hands the draft back to whoever called it, because the decision to publish under your GitHub account is yours. This key is how a repository gives that up standingly — any skill or agent that invokes the skeptic here can then publish a review under the invoking user's account, notifying every collaborator, with no preview. That's the right trade when a review loop needs threads to reply to, and it isn't part of the minimal setup.
It's deliberately the one key that doesn't follow the usual merge rules: it counts only from this file, committed, read at the PR's base ref. Not from ~/.claude/, not from an uncommitted copy in your tree. So a PR can't grant itself the right to publish in its own diff, the permission is visible and revocable by everyone who works on the repo, and it can't ride your machine's user-level config into someone else's project. It never overrides "don't post", never posts on a merged or closed PR, and confirm_before_posting: true cancels it outright.
/laterNo per-project config. Installed as a plugin (Option A), there is nothing to
set up — the SessionStart hook ships declared in .claude-plugin/plugin.json.
Installed by symlink or copy (Options B and C), add the hook by hand, once,
to <claude-config>/settings.json. Capture writes to a store, and later.sh list
will read it back on demand, but nothing replays it unprompted — which is the
half that makes the skill worth having — unless the hook is wired up:
{
  "hooks": {
    "SessionStart": [
      {
        "hooks": [
          {
            "type": "command",
            "command": "sh \"$HOME/.claude/skills/later/later.sh\" hook",
            "timeout": 5
          }
        ]
      }
    ]
  }
}
Wired this by hand before, ending in show? Change it to hook: show still
works, but its digest reaches only the model and never your screen.
Use a literal path to wherever you installed the skill. The block above
spells out the default ~/.claude; if you have set CLAUDE_CONFIG_DIR,
substitute it yourself in both the settings file you edit and the path inside
the command — neither follows it on its own. A
project's own .claude/settings.json works too, but then the digest only
appears in that one project — including the user-level store, which is the half
meant to follow you between projects — and that file is committed, so the hook
ships to collaborators who do not have the skill installed;
.claude/settings.local.json is the uncommitted equivalent.
${CLAUDE_PLUGIN_ROOT} does not work in your own settings:
it's substituted only for hooks a plugin declares itself, and elsewhere the
token reaches the shell as an unset variable and expands to empty — so the hook
silently runs sh "/skills/later/later.sh" forever.
Assume any mistake here is silent — the wrong file, a wrong literal path,
and ${CLAUDE_PLUGIN_ROOT} all fail with no error. The skill won't go
hunting for your hook or offer to write one: whether one exists can't be settled
by reading files (hooks are valid in several settings files, a plugin manifest,
or a plugin's hooks/hooks.json), and a hook written into a plugin's
version-stamped cache path would break on the next update.
Installed by symlink or copy, the skill folder also loads as a Claude Code mod
that lists parked items in a band above the prompt;
/later-pane opens them in a side pane. The plugin install gets neither.
skills/later/INSTALL.md has the same instructions
alongside the skill, plus a Windows note and what does and doesn't carry over to
OpenCode.
Nothing is stored in your repositories. Repository-scoped thoughts live at
<claude-config>/projects/<mangled-repo-root>/later.md, beside that project's
memory/ directory, and user-level ones at <claude-config>/later.md — so
they're never a diff, never a collaborator's problem, and never deleted along
with a worktree when its branch lands. <claude-config> is CLAUDE_CONFIG_DIR
where you've set it, and ~/.claude otherwise; later.sh path prints the
resolved location.
If you want to add to this collection (or fork it for your own), these are the rules I'm holding myself to:
/translate-strings and /translate-content are separate because XML resources and prose are different domains with different rules — better than one /translate with internal dispatch.~/.claude/skills/ — everything it needs lives inside the folder. Reference bundled files from SKILL.md by paths relative to SKILL.md (the documented supporting-files pattern; Claude resolves them against the skill's own directory, not the working directory). Files executed from a bash-injection command use the ${CLAUDE_SKILL_DIR} substitution, since the working directory at run time is the project root. No absolute ~/.claude/... assumptions. It doesn't demand tools a typical user wouldn't have; where a real dependency exists (gh, jq), it's stated, not silently assumed.CLAUDE.md.Issues and PRs welcome. If you want to add a skill, please follow the principles above — small, single-purpose, self-contained, and scoped to one job (don't reach outside what the skill is actually for).

了解快取的 /loop worker 與 CronCreate 背景自動化。ruflo 系列每個週期性工作都使用的基礎外掛。

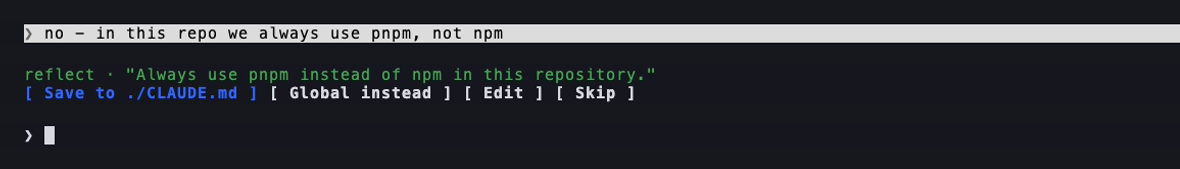
作為 Claude Code mod 的 claude-reflect:每個簡短提示都會進行模型檢查,找出可重複使用的修正(任何語言皆可);提示列上方的橫條讓你按一次就將它們儲存到 CLAUDE.md。

Claude Code 裡的早期 crit:在面板中評論對話、差異或檔案,把審查送給 Claude,並在線程中閱讀 Claude 的回覆。