
pierrebelin@pierrebelin
pierrebelin/claude-code-toolkit/tree/main/skills/context-band
面向 .NET / DDD 的 Claude Code 工具包範例:spec → plan → TDD implementation → audit 的 skill 鏈、依路徑限定的規則、agent 和 hook,透過把資料夾 cherry-pick 到 .claude/ 中安裝。
pierrebelin/claude-code-toolkit/tree/main/skills/context-band
這是一個面向個人 .NET / DDD / clean-architecture 專案的 .claude 起始工具包,包含 11 個 skill、4 個 subagent、6 條依路徑限定的規則、13 個 hook、狀態列,以及評估/支援程式。context-band 入口位於 skills/ 下,與 spec → plan → implement-tdd → verify-ddd-tdd 鏈並列:每次只處理一個業務決策,產出 SPEC-feature.md;plan-implementation 將批次拆成 PLAN.md 和每批的工作表;implement-tdd 透過 tdd-test-author subagent 編排 RED 測試,再由 tdd-implementer 完成 GREEN/REFACTOR;接著 verify-ddd-tdd 以唯讀方式稽核,再進入下一批。工具包還附帶 hook 註冊、啟動裁剪設定範例、coverage/audit/cost Python 程式,以及適配 {{PRODUCT}} 路徑的對照表。
請先查看作者 README,確認 marketplace 與外掛名稱;指令可能隨儲存庫結構而變動。
claude plugin marketplace add pierrebelin/claude-code-toolkit
claude plugin install context-band
My starting .claude folder. What I copy into a new .NET / DDD / clean-architecture repo so that Claude Code works the way I want from the first session: agents, layer rules, hooks, TDD skills, statusline.
No application code here. Nothing to build, nothing to test — only .md, .sh and JSON.
Four skills in a chain. Each step produces a file the next one reads — nothing travels through the conversation context, and no step starts without the previous one's artefact.
flowchart LR
    S["/business-spec<br/>one decision at a time"]
    P["/plan-implementation<br/>splits into batches"]
    I["/implement-tdd batch FX<br/>orchestrates the TDD"]
    V["/verify-ddd-tdd<br/>audits, read-only"]
    N(["next batch"])

    S -->|"SPEC-feature.md<br/>RM-XX, CU-XX<br/>zero technical detail"| P
    P -->|"PLAN.md<br/>+ one sheet per batch"| I
    I -->|"green batch<br/>TDD evidence ticked"| V
    V -->|"VALID"| N
    V -->|"gaps"| I
    N -.->|"next sheet"| I
/implement-tdd is not a step but a loop: one full turn per business behaviour, in the order Domain → Application → Infrastructure → WebAPI. Behaviours whose target test files are disjoint are grouped into a wave: their REDs go out as several Agent calls in a single message. GREEN never parallelises — two implementers on the same layer collide.
flowchart LR
    I["/implement-tdd"] --> R
    R["RED"] -->|"compact contract:<br/>RM/CU, scenario, level"| A["tdd-test-author subagent<br/>applies /tests-unit-tests,<br/>-integration, -contract or -e2e"]
    A -->|"red test<br/>no production code"| R
    R --> G["GREEN + REFACTOR"]
    G -->|"compact contract:<br/>red test, signatures,<br/>invariants, expected cost"| B["tdd-implementer subagent<br/>writes the production code<br/>tests read-only"]
    B -->|"green + cost stated<br/>or BLOCKED"| G
    G --> C["COST<br/>validated by the orchestrator"]
    C -.->|"next behaviour"| R
    C ==>|"whole batch green"| V["/verify-ddd-tdd"]
Five points carry all the rest:
/implement-tdd writes neither its tests nor its code. RED goes to the tdd-test-author subagent, allowed to touch test files and nothing else. GREEN and REFACTOR go to tdd-implementer, for which test files are read-only: a test that cannot go green without being modified comes back as BLOCKED instead of being weakened. The orchestrator produces nothing — it splits, reads the diffs, validates the cost and settles the design.BLOCKED and is a plan gap. Same rule on the GREEN side, plus one: a GREEN contract carries the current behaviour only — a guard written ahead turns the next RED green, and the only way out is to strip the code and re-observe the red.COST is a phase, not a review. No test measures the number of Infrastructure calls: green proves nothing on that axis. An await on a repository inside a loop goes back to design./verify-ddd-tdd runs before the next batch, in a fork and with no write access. It audits the delivered code as it is first, and only then its conformance to the plan — the plan is not the ultimate reference, it gets corrected mid-batch. The orchestrator hands it a capture produced by scripts/audit-capture.sh (status, diff, coverage, build and ArchitectureTests exit codes) and the sheet's FX section: the audit opens that once instead of rebuilding it over thirty turns. On a re-audit after correction, resume narrows the scope to the previous verdict's deviation table plus the diff produced since — what already carries a verdict is not re-established.This kit encodes my way of working, not a universal best practice. Among other things it imposes:
/// doc included;guard-git.sh module blocks add / commit / push);CLAUDE.md per handler folder, with a business-rules ↔ tests table checked by a hook;greps substituted by graphify explain when the AST graph actually answers.On another project, with other conventions or another tolerance for ceremony, half of these constraints are noise. Taking the kit wholesale mostly leads to fighting it.
The use I recommend: cherry-pick. A hook, a path-scoped rule, the structure of a skill, the traceability mechanism. The bricks are independent — except skills/, which refers back to rules/.
| Folder | Contents | Install target |
|--------|----------|----------------|
| agents/ | tdd-test-author (writes the RED tests), tdd-implementer (writes the production code in GREEN), ddd-tdd-auditor (audits a batch, read-only), adversarial-reviewer (tries to refute a spec, a plan or the next batch sheet before any code, read-only; returns closed questions ranked Blocking / Major) | <repo>/.claude/agents/ |
| rules/ | 6 path-scoped rules: domain, application-cqrs, infrastructure-ef, webapi-endpoints, tests, markdown-output (produced vs. instruction files, frozen literals) | <repo>/.claude/rules/ |
| docs/ | CONTEXT-COST.md (why the cost is quadratic, reading and batching rules, weekly protocol, session hygiene), TOOLING.md (RTK, graphify, worktrees, bootstrap). Opened on demand — CLAUDE.md keeps the standing rules and points here | <repo>/.claude/docs/ |
| hooks/ | 13 hooks: the Bash dispatcher (Git guard, cat/diff bounds, integration-suite filter, output filters, RTK rewrite), Agent guard, Read bounds, /implement-tdd relaunch and effort guard, aggregate blast radius, caveman forcing, rules ↔ tests traceability, subagent report shape, AST graph resync, worktree graph link, context load log, session cleanup, replayed-context step nudge | <repo>/.claude/hooks/ |
| lib/ | what the hooks call but the harness never invokes: the 6 dispatcher modules and their two output filters, the batching nudge, the shared bound body, the delegation nudge, the graph freshness helper, the context log reader | <repo>/.claude/lib/ |
| skills/ | 11 skills: the spec → plan → implementation → audit chain, 4 test skills, the monthly quality report, bulk-read and learn | <repo>/.claude/skills/ |
| settings.json | hook wiring + statusline + base permissions | <repo>/.claude/ (merge if the file exists) |
| settings.local.example.json | startup trim: the four keys that drop the claude.ai connectors, the synced skills and plugins, and the Workflow tool from every session | merged into <repo>/.claude/settings.local.json (installation step 3) |
| statusline-command.sh | git branch, model, context %, effort, 5 h rate limit, caveman badge, graph lag; also drops the current effort in $TMPDIR — the only channel that carries .effort.level, which implement-tdd-guard.sh reads back | <repo>/.claude/ |
| .gitignore | the runtime files the hooks write inside .claude/ | <repo>/.claude/ (merge if the file exists) |
| tools/ | bulk-read (one-shot, tool-less haiku worker answering a question over files you can already name — ~500 fixed tokens, the files never enter the calling context), doctor (read-only readiness check: binaries, registrations, git hook, graph, worker login, /tmp leftovers, /learn backlog as a NOTE; runs --quiet on SessionStart, silent when healthy save for that NOTE) | <repo>/.claude/tools/ |
| evals/ | run.sh + cases/*.json: recorded hook payloads replayed through the hooks, checking the decision, the rewritten command, the appended prompt or the injected context (~30 s). Every hook case is also timed: a hook whose median latency exceeds its budget fails the run like a wrong decision (LATENCY_MAX_MS, 80 ms by default; LATENCY_SLOW_HOOKS for the per-hook exceptions, handler-claude-md-check.sh at 300 ms). Every defect found in production is a case; a hook change without a case is not finished | <repo>/.claude/evals/ |
| scripts/ | rules-coverage.py (rules ↔ traits, repo-wide; --ids <sheet> lists the DDD/APP/PERF ids the sheet never cites), untagged-tests.py (tests carrying no trait), migrate-rm-traits.py (one-shot: Tests column → traits), turn-batching-check.py (tool-call batching, context fill per tool, read-bounds denials and forcings; --save-baseline / --compare to track a week against a frozen snapshot, --until to freeze one before a change goes live), quality-report-check.py (arithmetic of a quality report), audit-capture.sh (gathers the deterministic audit material — status, diff, RM/CU and DDD/APP/PERF coverage, build, ArchitectureTests — into one file, so /verify-ddd-tdd opens it once instead of rebuilding it over thirty turns), pre-audit.sh (the mechanical gate before /verify-ddd-tdd: unclassified DDD/APP/PERF ids, comments under src/, files outside the batch, traits, closed sheet, whitespace, handler tests asserting a spy or a double's state instead of the result and SavedEvents — red means no fork), access-cost.py (awaited Infrastructure calls of the files given, read off the syntax tree with the ast-grep rules under scripts/access-cost/; loop, lambda and in-memory filter flagged; --diff scans every modified .cs under src/ and tells added lines from pre-existing ones — the Cost line the COST step states and the Cost axis judges), install-git-hooks.sh (installs .git/hooks/post-checkout, which links the gitignored settings.local.json into every new worktree — only needed when the hook registration was moved out of the committed settings.json), batch-wallclock.py (wall clock of an /implement-tdd batch: model, tools, agent wait and human, turns after the first audit, audit durations, and --subagents for the per-type table, with tokens read and written per run and a main chain row for the orchestrator's share), learn-candidates.py (the model-free half of /learn: extracts the Blocking / Major rows of past ## Verdict — GAPS, remembers what was treated or refused in .claude/learn-state.json, --count feeds the doctor NOTE; --memory lists the mechanical defects of the auto-memory — index doubles, orphans, dead links, cited repo paths gone) | <repo>/scripts/ |
Copy the folders you want into <repo>/.claude/. The skills read .claude/rules/*.md: copying skills/ without rules/ breaks their references. scripts/ is the exception: it goes to <repo>/scripts/, which is where the hooks and the skills reference it.
The kit ships the .gitignore covering what the hooks write inside .claude/: context-log.tsv, context-log.raw.json, settings.local.json, learn-state.json (the /learn cache), evals/.fixtures/ and Python byte-code. One entry belongs to the repo's own .gitignore, one level up: graphify-out/, the AST graph rebuilt by graphify-autosync.sh.
Wire it up — copy settings.json to <repo>/.claude/settings.json, or merge its hooks and statusLine keys into the existing file. The commands there are written with $CLAUDE_PROJECT_DIR, never an absolute path: that is what makes the setup portable.
The shipped settings.json is a shareable template, not a settings.local.json: no one-off session grant, no machine path, no skillOverrides bound to skills absent from the kit. Its allow list covers the strict minimum (Edit, WebSearch, dotnet, rtk, gh pr, xargs, python3, graphify query|explain|path, git check-ignore). Broad grants — Bash(rm *), Bash(cd *) — are deliberately excluded: adding them means letting an agent delete outside its scope.
Keeping the hooks to yourself instead? Move the hooks key to .claude/settings.local.json (gitignored) and run bash scripts/install-git-hooks.sh once per clone — without it, no project hook fires inside a worktree, since the worktree carries the scripts but not their registration. See docs/TOOLING.md.
Trim the startup — merge the four keys of settings.local.example.json into <repo>/.claude/settings.local.json (create it if missing; it is gitignored). Use the Edit tool, never a script: the auto-mode classifier refuses a script on that file. The syncClaudeAi* keys are never read from .claude/settings.json, only from settings.local.json or the user settings.
| Key | Drops | Keep it off when |
|---|---|---|
| disableClaudeAiConnectors | every claude.ai MCP connector — all or nothing | the repo relies on one of them |
| syncClaudeAiSkills: false | the synced anthropic-skills:* (docx, pdf, xlsx, pptx, browser…) — skillOverrides does not reach them | a skill or spec flow produces or reads those formats |
| syncClaudeAiPlugins: false | the synced plugins (cowork-plugin-management) | a workflow uses them |
| disableWorkflows | the Workflow tool (~5k tokens), and with it the ultracode keyword | the repo uses either |
Check usage before cutting: a key whose feature the repo depends on stays out. Measure from the repo root before and after, then validate the file with python3 -m json.tool .claude/settings.local.json:
claude -p "ok" --output-format json --max-turns 1 </dev/null \
  | python3 -c "import json,sys;u=json.load(sys.stdin)['usage'];print(u.get('input_tokens',0)+u.get('cache_creation_input_tokens',0)+u.get('cache_read_input_tokens',0))"
Measured on a .NET repo of this shape: 35.4k → 22.6k tokens per claude -p startup (−36 %), reloaded on every /clear.
Substitute {{PRODUCT}} and adapt the points below, otherwise the rules never load and the traceability hook finds nothing.
The kit comes from a real repo. The product name has been replaced everywhere by the {{PRODUCT}} placeholder:
src/{{PRODUCT}}.Domain/          namespace {{PRODUCT}}.Application.Catalog.Products;
tests/{{PRODUCT}}.UnitTests/     dotnet test --project tests/{{PRODUCT}}.UnitTests/…
One substitution is enough to make the kit operational:
grep -rl '{{PRODUCT}}' .claude/ scripts/ | xargs sed -i '' 's/{{PRODUCT}}/MyProduct/g'
The code examples rest on a neutral fictional domain — aggregates Product and ModuleDiagram, sub-entities ProductItem and DiagramNode, bounded contexts Catalog and Studio. Nothing there matches an existing project. Rewriting them with the target domain's vocabulary makes the examples more telling, but is not needed to make things work.
The kit assumes a repo shaped as src/{{PRODUCT}}.<Layer>/ + tests/{{PRODUCT}}.<Suite>/. Without that shape, adapt at least:
| File | Line(s) | What to change |
|------|---------|----------------|
| rules/domain.md | paths: frontmatter | Domain project glob |
| rules/application-cqrs.md | paths: frontmatter | Application project glob |
| rules/infrastructure-ef.md | paths: frontmatter | Infrastructure + migrations globs |
| rules/webapi-endpoints.md | paths: frontmatter | WebAPI + public/SDK contract globs |
| rules/tests.md | paths: frontmatter | tests glob |
| hooks/handler-claude-md-check.sh | APP, BOUND_SUITES | paths of the Application, UnitTests and ContractTests projects |
| scripts/rules-coverage.py | APP, BOUND_SUITES | same paths |
| scripts/migrate-rm-traits.py | APP, TESTS | Application and tests roots; no suite binding, it reads every suite |
| scripts/untagged-tests.py | PRODUCT | project prefix stripped from the suite name |
| lib/graphify-freshness.sh | scanned dirs, extensions | indexed languages and folders |
| hooks/caveman-skill-ultra.sh | case "$skill" | skills that must force caveman=ultra |
| agents/tdd-test-author.md, agents/tdd-implementer.md | dotnet test command | test project path pattern |
| skills/implement-tdd/references/test-scope.md | {{PRODUCT}}, test environment variable, namespace roots, filter examples | projects, suites actually present, integration test splitting |
| skills/quality-report/commands-dotnet.md | {{PRODUCT}}, suite list, SonarQube project key, Stryker config names | the suites actually present, the Sonar key, the mutation configs |
| skills/quality-report/commands-js.md | Jest config paths, build script, src/pages | the front-end layout of the target repo |
| settings.json | permissions.allow | tools specific to the target repo |
| skills/*/SKILL.md, skills/*/references/*.md | code examples | namespaces and aggregate names |
| scripts/audit-capture.sh | {{PRODUCT}}.sln, ArchitectureTests project path | solution name and architecture suite of the target repo |
| docs/TOOLING.md | ## Bootstrap section | restore command, --no-restore policy, purge, per-OS SDK paths |
| docs/CONTEXT-COST.md | the measured figures | re-measure with turn-batching-check.py, then create .claude/context-baseline.json (--until <date> --save-baseline) |
| rules/markdown-output.md | language of the produced family | the language the team proofreads; the frozen literals never move |
The graphify-* scripts derive the repo root from dirname "${BASH_SOURCE[0]}": no absolute path to fix, but they assume the .claude/hooks/ and .claude/lib/ depth — both one level under .claude/. Override with GRAPHIFY_REPO.
| Hook | Event | Role | Blocking |
|------|-------|------|----------|
| bash-dispatch.sh | PreToolUse:Bash | single entry point: parses the payload once, then runs lib/guard-git.sh, lib/guard-cat-bounds.sh, lib/guard-diff-bounds.sh, lib/guard-integration-filter.sh, lib/rewrite-piped-filter.sh (twice: profiles graphify-query then git-grep) and lib/rewrite-rtk.sh in that order. First module that answers wins, so a rewrite is never rewrapped by the RTK rewrite; lib/guard-graphify-grep.sh sat in second position until 2026-09-13 — it ran graphify explain on every symbol-looking grep to decide, 2.25 s a call for one substitution over 60 sessions; the two output filters sit before it because rtk hook claude has no rewrite of its own for graphify or git grep. lib/batching-nudge.sh runs outside that chain: it decides nothing, and its advice is grafted onto whatever the chain answers | depends on the module |
| explore-guard.sh | PreToolUse:Agent | delegation guard, two checks in cost order: every Agent call carries a description; the model is chosen rather than inherited — haiku required on Explore, merely explicit on general-purpose, which also writes. Since 2026-09-17 the check reaches every spawn: a call with no subagent_type is read as general-purpose — it used to fall through the type filter and inherit Opus, which is where the mechanical refactors were billed — and a custom agent is asked for a model unless its own file pins model: in frontmatter. When both pass it appends the report contract to tool_input.prompt (caveman-ultra, 20-line cap, 40 for Plan): additionalContext would land in the caller's context, only the prompt reaches the agent. Own hook: a spawn costs ~55k startup tokens, a grep ~300, and the agent's final report is re-injected whole into the caller | yes |
| implement-tdd-guard.sh | UserPromptSubmit + PreToolUse:Skill | denies a second /implement-tdd launch in a session that already closed a batch — it reads the transcript for the closing literal of the skill (French and English wordings both matched). Correction mode passes. Re-issuing the identical launch passes through; the chained batch would otherwise pay the whole accumulated context of the previous one, measured at 1.9x the input at equal request count. Also denies a launch at effort high, xhigh or max, reading the level the statusline dropped in $TMPDIR: the orchestrator runs 100 to 180 turns at 8.6 s each there, and only /effort can change it | yes, once per closed batch and once per launch at too high an effort |
| read-bounds.sh | PreToolUse:Read | denies a Read with no offset/limit on a file past 120 lines or 8 kB (CLAUDE_READ_BOUNDS_THRESHOLD, CLAUDE_CAT_BOUNDS_BYTES), and records the denial per agent. The refusal names tools/bulk-read as the third way out, for a question about the file rather than an edit. Re-issuing the identical Read passes through — that is how a full read is forced; the pass applies to the agent that asked for it, not to its siblings or its parent. Skips images, PDFs and notebooks. On the reads it lets through it sources lib/delegation-nudge.sh, which counts them | yes, once per file and agent |
| affected-blast-radius.sh | PreToolUse:Edit\|Write | on a Domain aggregate or value object (*.Domain/*/Aggregates/*.cs, .../ValueObjects/*.cs), runs graphify affected on the edited type and injects the per-project rollup as additionalContext — never the raw output, 421 lines / 65 kB on a central id against 8 rolled-up lines. Resolves the ambiguity graphify 0.9.58 introduced by path-qualifying node ids, using the edited file as its own disambiguator, and stays silent when the symbol still does not resolve. Once per (agent, symbol) | no |
| caveman-skill-ultra.sh | PreToolUse:Skill | forces caveman=ultra when entering certain skills | no |
| handler-claude-md-check.sh | PostToolUse:Edit\|Write | cross-checks the ## Règles métier table of the handler CLAUDE.md files against the tests actually present; reports untested rules and orphan tests. Speaks through hookSpecificOutput.additionalContext: on PostToolUse, plain stdout at exit 0 reaches the transcript only, never the model — 231 reports went unread that way before 2026-09-13 | no, warning only |
| graphify-autosync.sh | Stop | rebuilds the graph if the working tree moved. mkdir lock, anti-shrink guard (auto --force if the drop is ≤ 2 %) | no |
| subagent-report-shape.sh | SubagentStop | checks the SHAPE of a ## RED / ## GREEN report — required lines, observed exit code on the Command line, | Test | Case covered | table — and blocks with a reason so the agent re-emits a complete report from the context it still holds, instead of costing the orchestrator a turn plus a SendMessage (1 to 4 per batch). Form only: a non-empty diff or an unexpected exit code is the orchestrator's call, never the agent's. stop_hook_active closes the loop; ## BLOCKED and every other agent pass untouched | yes, once per malformed report |
| worktree-graphify-link.sh | SessionStart | symlinks the main working tree's graphify-out/ into a linked worktree. graphify resolves its graph only at <cwd>/graphify-out/graph.json — no parent lookup, no env var — so query, explain, path and affected all fail in a worktree without it. No-op outside a linked worktree | no |
| session-cleanup.sh | SessionStart | drops this session's substitution and read-denial memories (glob, subagents included), purges what is older than two days | no |
| context-log.sh | InstructionsLoaded | logs every instruction file entering the context (path, bytes, ~tokens, load reason) into .claude/context-log.tsv | no, observes only |
| clear-nudge.sh | UserPromptSubmit | reads the last assistant usage in the transcript and, at every 150k-token step of replayed context (CLAUDE_CLEAR_NUDGE_STEP), appends one line of additionalContext asking the model to tell the user that /clear is due if the phase is done | no |
The lib/ side, which the harness never calls directly:
| File | Called by | Role |
|------|-----------|------|
| lib/guard-git.sh | bash-dispatch.sh | forbids mutating Git commands (add, commit, push), including through rtk git, git -C, cd && git. Reading stays free; add -N and apply fall through to ask for the worktree hand-back |
| lib/guard-cat-bounds.sh | bash-dispatch.sh | denies a bare cat, head or tail on a file past 120 lines (CLAUDE_READ_BOUNDS_THRESHOLD) or 8 kB (CLAUDE_CAT_BOUNDS_BYTES) — the byte trigger catches Markdown that wraps at the paragraph, where a line count alone waves an 18 kB report through. read-bounds.sh is a PreToolUse:Read hook and has no reach over Bash; measured on one .NET batch, Read fell to 1 % of the context fill while Bash rose to 85 %. head/tail count for the span they ask for: head -20 f passes, head -n 5000 f or tail -n +1 f is a dump in disguise. Never fires on a pipe, a redirect, a binary format, or a second identical command from the same agent |
| lib/guard-diff-bounds.sh | bash-dispatch.sh | denies git diff, git show and git log -p when nothing bounds the output and the patch passes 400 changed lines (CLAUDE_DIFF_BOUNDS_LINES). Added 2026-09-17, after a 14-day measurement: rtk compresses the dotnet side well — dotnet build -59.5 % over 1 295 calls, dotnet test -95 to -100 % — but not a patch, and a bare git diff on a working tree of the day was 109 kB, ~27 k tokens carried to the end of the session. The size is measured, not guessed: the same command is re-run with --numstat, so a three-line diff is never refused, at the price of a second git call (~50 ms). LC_ALL=C on that sum — BSD awk aborts on the first invalid byte sequence of a binary or latin-1 file, and an empty sum used to read as a small patch. --stat, --numstat, --shortstat, --name-only, --name-status, --quiet, a pipe, a redirect and a second identical command from the same agent all pass |
| lib/bounds-common.sh | sourced by read-bounds.sh and lib/guard-cat-bounds.sh | the shared body of the two bound guards: thresholds, the binary and instruction-file skip lists, the per-language outline, and the refusal layout. Extracted 2026-09-11 from ~45 lines duplicated between them — the outline block was identical down to the regexes, differing only in the variable holding the path. Cost was never the point, divergence was, and it had already happened: guard-cat-bounds skipped .zip and .nupkg where read-bounds did not, so a cat of a package passed while a Read of it was denied and handed a text outline of a binary. Callers keep only what genuinely differs: the tool named in the refusal and the two sentences telling the caller how to read a range and how to force |
| lib/delegation-nudge.sh | sourced by read-bounds.sh, reset by explore-guard.sh | counts the distinct .cs files the main chain read directly and appends one additionalContext nudge towards an Agent at the threshold, then at each doubling (6, 12, 24 files — CLAUDE_DELEGATION_NUDGE_THRESHOLD). Never denies: any single read is legitimate, only the accumulation is not. A denied read never entered the context, so it is not counted, and a subagent's own reads never count either — delegation is the outcome wanted. Every Agent spawn restarts the window rather than silencing it for the session: one Explore at turn 2 followed by thirty direct reads used to buy permanent silence. Was hooks/delegation-nudge.sh until 2026-09-12, a second hook on the Read matcher — the pair cost 31 ms per Read in jq spawns alone |
| lib/guard-integration-filter.sh | bash-dispatch.sh | denies a dotnet test on the IntegrationTests project carrying neither --filter-class nor --filter-method, subagents included — a whole run was measured at 602 s, twice, where the impacted context fits in one filtered minute. rtk, cd &&, env assignments and redirections pass; only the project and the presence of a filter are inspected |
| lib/rewrite-piped-filter.sh | bash-dispatch.sh | appends a local stdout filter to a command RTK cannot shrink, one profile per filter. graphify-query pipes a bare graphify query through lib/graphify-query-filter.sh, which drops sourceless nodes and community=X and collapses [src=PATH loc=LNN] to the clickable PATH:NN — measured -14 to -30 % across two .NET repos, every source-carrying node preserved; explain is left alone, a few hundred bytes with nothing to trim. git-grep pipes git grep through lib/git-grep-filter.sh, which turns the repeated path into a per-file header — lossless, rebuilding path:NN:content from the grouped form diffs byte-identical against the raw output, and the gain follows path length against content length (-32 to -48 % on a .NET tree with ~130-character paths, -6 % on this repo). Both fire only when the LAST segment of the command is the bare match, so cd x && graphify query "y" counts; any pipe, redirect or substitution leaves the command alone, which is the escape hatch. Merged 2026-09-11 from rewrite-graphify.sh and rewrite-git-grep.sh: the two differed only by a trigger regex and a filter path |
| lib/graphify-query-filter.sh | piped by lib/rewrite-piped-filter.sh (profile graphify-query) | stdout filter of graphify query: drops sourceless nodes and community=X, collapses [src=PATH loc=LNN] to PATH:NN |
| lib/git-grep-filter.sh | piped by lib/rewrite-piped-filter.sh (profile git-grep) | stdout filter of git grep: one header per file instead of the repeated path, lossless |
| lib/rewrite-rtk.sh | bash-dispatch.sh | strips the /usr/bin/, /bin/, /usr/local/bin/ prefix off grep/rg/find/egrep/fgrep, prefixes dotnet test\|restore\|format with rtk in command position (rtk hook claude only rewrites dotnet build, though the rtk dotnet filter accepts all four), then pipes the payload to rtk hook claude itself. When rtk answers nothing on an already-prefixed command, the module emits the updatedInput decision itself. The kit is the RTK rewrite plus the normalisation — a repo installing it needs no global rtk init -g |
| lib/batching-nudge.sh | bash-dispatch.sh | appends one line of additionalContext when the last 6 tool-carrying turns each held a single call (CLAUDE_BATCHING_WINDOW, CLAUDE_BATCHING_COOLDOWN). Never denies, never rewrites. Wired on Bash but reads the transcript, so it counts every tool. Main chain only: a subagent drops its context after ~30 turns, where the same run costs 32x less |
| lib/graphify-freshness.sh | autosync + statusline | counts the sources newer than graph.json, 20 s TTL cache |
| lib/context-report.sh | run by hand | reads the context log back: heaviest files, tokens per load reason. --session narrows it to the last session |
rtk gain prints [warn] No hook installed even when this hook is active, and rtk init --show prints [--] Hook: not found. Both detectors only inspect ~/.claude/settings.json; a hook declared in a project .claude/settings.local.json is invisible to them. Trust the rewrite, not the warning — echo '{"tool_name":"Bash","tool_input":{"command":"grep -rn foo src"}}' | rtk hook claude must answer with an updatedInput carrying rtk grep./usr/bin/grep -rn foo src, rtk hook claude returns nothing at all, where the bare grep gets rewritten.rtk hook claude is idempotent — rtk git status comes back unrewritten, so a global RTK hook (rtk init -g --auto-patch) and this one never produce rtk rtk git status. Register only one of them anyway. Both fire on the same tool_input, and on a symbol-discovery grep the global one answers rtk grep … while the dispatcher answers graphify explain "X" — two competing updatedInput with no defined winner. The dispatcher already performs the RTK rewrite: drop the global hook.command builtin. command grep … is not stripped by the normalisation.rtk grep answers with a match count, not the matching lines. Repo-wide it pays; on a single short file it costs a turn to re-read with awk.Main chain: business-spec → plan-implementation → implement-tdd → verify-ddd-tdd.
| Skill | When |
|-------|------|
| business-spec | short, testable business spec, no technical design; adversarial-reviewer reads it fresh, every Blocking open question is put to the user |
| plan-implementation | validated spec → DDD plan split into batches, tracing RM/CU and decisions; refuses to start while the spec carries a Blocking open question, ends with an adversarial-reviewer pass |
| implement-tdd | implements an all-layer batch under strict TDD; delegates RED to tdd-test-author, GREEN and REFACTOR to tdd-implementer |
| verify-ddd-tdd | audits the batch before moving to the next one; runs in a fork on ddd-tdd-auditor. full widens to the touched boundaries, resume re-audits only the deviations of a previous verdict |
| tests-unit-tests | handlers/services: business rules, query results, command events |
| tests-integration-tests | repositories / persistence, Testcontainers |
| tests-contract-tests | public HTTP contract, Verify snapshots |
| tests-e2e-tests | lifecycle of at least two operations, never an isolated endpoint |
| bulk-read | a question over files you can already name, answered by tools/bulk-read without the files entering the calling context |
| quality-report | monthly quality snapshot: tests, coverage, SonarQube, Stryker, git activity — .NET or JS/TS |
| learn | when doctor prints NOTE learn (gaps untreated across at least two batches): groups the gaps recurring in past verdicts (≥ 3 batches, at most 3 motifs per axis) into motifs, writes each accepted one into a rule, an audit criterion or a mechanical check and retires the lines it makes useless; /learn memory audits the auto-memory for stale, duplicated or contradictory entries |
Layer separation — the Domain depends on nothing (no HTTP, no EF, no DTO). Application orchestrates: load, call the Domain, save the events, return. Infrastructure and WebAPI translate IO and carry no business rule. Resource bounds sit at the WebAPI boundary, never in Domain nor in Application.
The rules/*.md files are the single source of the layer conventions. They load when a matching file is opened. Naming tables live in the rule of the layer that owns the artefact — nowhere else. Two sources that drift make the choice random.
Strict TDD — Red-Green-Refactor. The red test precedes the code, the REFACTOR phase cleans up then deletes (a defensive branch made impossible by an invariant, an indirection with a single caller, dead code introduced by the batch).
Surgical change — every modified line ties back to the behaviour at hand. No improvement of adjacent code that worked, no renaming or reformatting outside scope, no flexibility "for later". An adjacent bug outside scope is reported, not fixed. verify-ddd-tdd audits that axis hunk by hunk: a hunk with no owning RM/CU is a gap, even if it improves the code.
Zero comments in production, XML /// doc included — intent is carried by naming. Pre-existing comments explaining a decision, a constraint or an exception are kept; only touch them within the lines you touch.
Rules ↔ tests traceability — every handler folder carries a CLAUDE.md with a ## Règles métier table, and every test declares the rule it covers on itself: [Trait("RM", "{HandlerFolder}/{RM|RL-xx}")]. handler-claude-md-check.sh checks both directions; scripts/rules-coverage.py gives the repo-wide count.
Never commit to Git. The user decides when to commit. lib/guard-git.sh makes the instruction deterministic.
Done checklist — never announce completion without: the relevant tests green, no regression, plan files marked ✅ with a date, the handler's ## Règles métier table up to date (Tests column included), the parent feature's index CLAUDE.md up to date if a handler is added or its intent changes.
Progressive disclosure inside a skill — what only one branch or one phase needs lives in its own reference file, read at that point and not before: correction-mode.md opens only on a — correction: argument, closing.md only after the audit verdict. A reference loaded at the top of a skill is carried by every turn of the batch.
Context discipline — these are behaviour rules, independent of the domain. They are not shipped by a hook: copy them into the CLAUDE.md of the repo installing the kit.
Context — every turn resends everything accumulated: the cost follows the number of turns and the size of what you leave in them.
- Independent calls → a single message. Two
Read/Bash/Grepthat do not wait on each other, in two turns, pay the accumulation twice. A turn = one billed round trip, not one call.lib/batching-nudge.shsays so out loud after 6 mono-call turns in a row — measured on one .NET batch: 110 of 124 tool-carrying turns held a single call, and the three heaviest cost lines of that session all scale with the turn count.- Bounds mandatory past 120 lines or 8 kB —
read-bounds.sh(PreToolUse:Read) denies an unboundedRead,lib/guard-cat-bounds.shan unboundedcat,lib/guard-diff-bounds.shan unboundedgit diff,git showorgit log -ppast 400 changed lines. Re-issue the same command verbatim to force the full read.- An aggregate read whole is ~24k characters carried to the end of the session: locate (
graphify,grep -n) then read the range. Measured on a .NET repo of this shape:Readis 30 % of context fill, and only a third of the calls are bounded.- 3 files or more to go through → haiku subagent: its reads stay in its own context, only the conclusion comes back.
Subagents
- Read-only exploration (
Explore,general-purposewhen searching) → alwaysmodel: haikuin theAgentcall. Without that parameter the agent inherits the parent model: measured at 11× the cost per turn for the same locating work.- Writing code, tests, multi-step → default model.
- Bound the report in the delegation prompt: format and max size. An agent's final report is re-injected whole into the main conversation — measured at 27k characters per unbounded
Explorelaunch, against 3k for an agent with an imposed format.- Correcting a returned agent:
SendMessageunder 3 turns, a freshAgentbeyond.SendMessageresumes the agent with its whole transcript, re-sent on every further turn; an agent stopped at 49 turns carries ~80k of context and every correction turn pays it. A fresh agent restarts at ~17k of preamble plus ~11k of reloaded rules. Measured: a 10-turn correction costs ~850k in continuation against ~350k restarted.- Never delegate a mechanical file operation (restore from HEAD, add an import to N files, rename, reformat): a Bash loop does it in one turn. Measured on two sessions: a
restore 19 files from HEADagent cost 11 turns, anadd an import to 11 filesagent 4 more.- Every
Agentcall carries adescription. Anonymous launches were 42 % of the subagent bill over those two sessions — no name is the symptom of a delegation that was never scoped.Symbol or relation → graphify; text → grep.
explain(what a node is, what it uses, who uses it),affected(what breaks if you change it),path(how A reaches B),query(natural-language question). The graph only holds AST nodes: a literal, an error message, a configuration value, a.md/.json/.csprojare not in it — that is grep. Never chaingrep | grep | head.Session hygiene — context cost is quadratic in the number of turns: every answer is re-billed as input on every later turn.
- Hard cap of 250k context tokens:
/clearwith a resume note even mid-phase. A/clearcosts ~51k of startup plus ~40k of re-reading, written to cache at 2×; dropping from ~250k to ~100k saves 150k re-read at 0.1× on every turn — paid back in about ten turns, against 70 to 160 for a long session./clearon a phase change — the only mechanism that throws away the accumulated tail. Within the hour, the head (system prompt, tools,CLAUDE.md) is read back from cache instead of being rewritten./branchbefore an uncertain exploration: a 30-turn dead end abandoned in a branch is never carried by the trunk./forkreduces nothing — it copies the conversation into a background session. A throughput tool, not a cost tool.- Never let
/compactfire: it injects ~60k tokens carried to the end ($3.60 on average over 18 sessions, $12.15 at worst)./clearwith a ten-line brief costs less.- The cache expires after an hour of inactivity. Resuming a large session after a long pause for a small question pays the full rewrite of the prefix — measured at $90 over 30 days.
Only jq and python3 really count. The rest degrades cleanly — and three of these tools are not public, they stay referenced because I use them.
| Tool | Required by | If missing |
|------|-------------|------------|
| jq | statusline, bash-dispatch.sh, graphify-autosync.sh, session-cleanup.sh, clear-nudge.sh, tools/doctor | silent statusline, no grep substitution |
| python3 | lib/batching-nudge.sh, handler-claude-md-check.sh, subagent-report-shape.sh, caveman-skill-ultra.sh, context-log.sh, clear-nudge.sh, tools/doctor, every script under scripts/ | inert hooks, exit 0 |
| perl | evals/run.sh (millisecond timer), tools/bulk-read, tools/doctor | no latency budget in the evals; shipped with macOS and most Linux distributions |
| claude CLI, logged in | tools/bulk-read | the refusals and /bulk-read still point at it; the worker exits with a clear message (claude not found, Not logged in) and the caller falls back to a bounded read |
| graphify (~/.local/bin/graphify) | affected-blast-radius.sh, autosync, freshness | no blast radius on an aggregate edit (the hook exits 0 in silence); autosync logs "graphify not found, skip" and exits 0 |
| rtk | lib/rewrite-rtk.sh, prefixed commands in the skills | drop the rtk prefix from the skills, nothing else breaks |
| caveman plugin (or its two node hooks kept outside it, see docs/TOOLING.md) | caveman-skill-ultra.sh, statusline badge | flag written with no effect |
Every hook exits 0 when its dependency is missing, except lib/guard-git.sh, explore-guard.sh, read-bounds.sh and implement-tdd-guard.sh which block by design. Removing the graphify-* scripts, read-bounds.sh and caveman-skill-ultra.sh from settings.json leaves a coherent kit; bash-dispatch.sh keeps working with any subset of its modules present.
Other repos configuring a coding agent, from other angles: RESOURCES.md.
MIT. Take what you want, closed-source projects included.

了解快取的 /loop worker 與 CronCreate 背景自動化。ruflo 系列每個週期性工作都使用的基礎外掛。

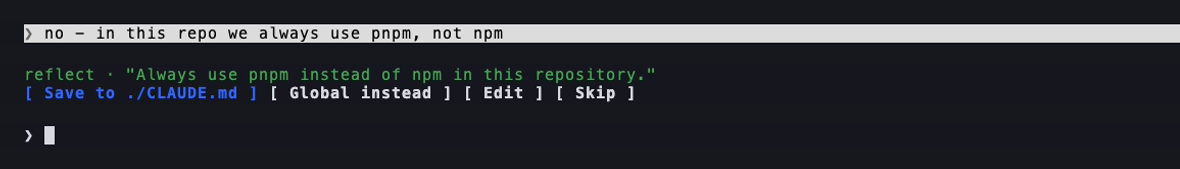
作為 Claude Code mod 的 claude-reflect:每個簡短提示都會進行模型檢查,找出可重複使用的修正(任何語言皆可);提示列上方的橫條讓你按一次就將它們儲存到 CLAUDE.md。

Claude Code 裡的早期 crit:在面板中評論對話、差異或檔案,把審查送給 Claude,並在線程中閱讀 Claude 的回覆。