krika2810@krika2810
krika2810/keep-cache-warm
一個 Claude Code 函式鉤子外掛,用來保持 1 小時的提示快取溫熱:閒置約 55 分鐘後,透過 $.model.fork 重播快取前綴,讓下一輪避免完整快取寫入,並設有 ping 上限與安全措施。
krika2810/keep-cache-warm
cache-keepalive 是一個 Claude Code mod(函式鉤子外掛),適用於 Claude Code 2.1.289,讓你暫時離開時,1 小時的提示快取不會冷掉。
運作方式:
turn.step,記錄每次主要執行緒模型請求的送出時間,只統計回應回報讀取或寫入快取的請求。$.model.fork,送出很短的「reply ok」提示,完全重送主要執行緒的上一個請求,讓 API 從快取提供整個前綴,並在不完整寫入快取的情況下重新開始該項目的 60 分鐘生命週期。安全措施:ping 上限(maxPings,預設 6,0 = 不限)、在 59+ 分鐘時跳過太晚的計時器、沒有快取命中時停止並顯示 toast、忽略子代理請求、不在工作階段中途 ping,以及失敗的請求不算預熱。
成本:一次 ping 按一次快取讀取,加上 fork 未快取的輸入/輸出(包括 thinking)計費。大多數模型的快取讀取費用是基礎輸入的 0.1 倍(部分模型更低)。沒有 ping 時,過期後的第一輪會以基礎輸入的 2 倍重寫整段對話,因此大型對話通常使用 keep-alive 比較便宜;但小型對話或 ping 次數很多時,成本可能更高。
用法:/cache-keepalive(狀態)、off、on、now。狀態列顯示 cache keep-alive: armed (n/6)。
透過 /config 或 pluginConfigs 設定選項:idleMinutes(預設 55,限制在 1-58)和 maxPings(預設 6)。
載入:claude --plugin-dir ./keep-cache-warm。驗證/測試:claude plugin validate . 和 claude plugin test .。授權採用 MIT。
請先查看作者 README,確認 marketplace 與外掛名稱;指令可能隨儲存庫結構而變動。
claude plugin marketplace add krika2810/keep-cache-warm
claude plugin install cache-keepalive
cache-keepalive: a Claude Code mod (function-hooks plugin) that keeps the 1-hour prompt cache from going cold while you step away.
Compatibility: Claude Code mods and function hooks are early access, and their API can change between Claude Code releases. This repository was tested against Claude Code 2.1.289. After upgrading, load the mod once so Claude Code rewrites its type definitions in
.claude-plugin/types/. Then re-runclaude plugin validate .andclaude plugin test ..
turn.step and records when each main-thread model request is sent. It counts only requests whose response reports cache reads or writes.$.model.fork with a tiny "reply ok" prompt. The fork resends the main thread's last request exactly (same model, system prompt, tool definitions and messages) with that prompt appended. The API serves the whole prefix from the cache, and the read restarts the entry's 60-minute lifetime without paying for another full cache write.maxPings pings in a row (default 6, about 5.5 hours) so an abandoned session doesn't keep spending. Set it to 0 for no limit.A ping is not free. It is billed as one cache read of the conversation, plus the fork's uncached input (its short prompt) and its output, including any thinking. A cache read costs 0.1× the base input price on most models, and less on some: 0.05× on Claude Opus 5.5 and 0.025× on Claude Fable 5.1.
Without the ping, the first turn after the cache expires writes the whole conversation to the cache again. With the 1-hour TTL, that write costs 2× the base input price. For a large conversation, a keep-alive read is usually much cheaper than that rewrite. The fork's own input and output costs don't shrink with the conversation, though, so on a small conversation, or after many pings in a row, keeping the cache warm can cost more than letting it expire. That is why maxPings caps the run.
/cache-keepalive           # status: minutes until the next ping, pings sent
/cache-keepalive off       # stop for this session
/cache-keepalive on        # resume
/cache-keepalive now       # ping immediately
The status line shows cache keep-alive: armed (n/6) while a countdown is running.
/config or pluginConfigs in settings)| Field | Default | Meaning |
| --- | --- | --- |
| idleMinutes | 55 | Minutes after the last cache-touching request before a ping (clamped to 1–58, so a ping is always due before the 59-minute cutoff) |
| maxPings | 6 | Pings in a row before giving up; 0 means no limit |
claude --plugin-dir ./keep-cache-warm
claude plugin validate .
claude plugin test .

Claude Code 外掛,會壓縮工具輸出、在壓縮前建立檢查點、評分內容品質,並在本機面板回報 token/成本節省;附帶 hooks 與 localhost 常駐程式。
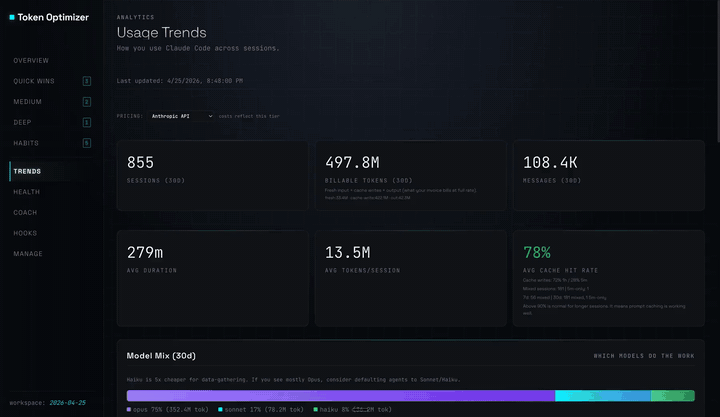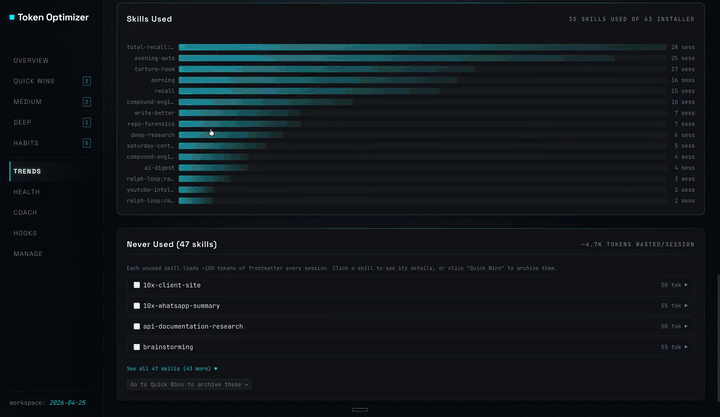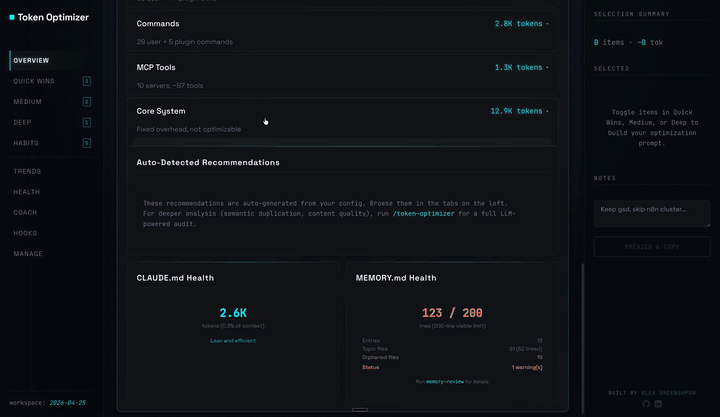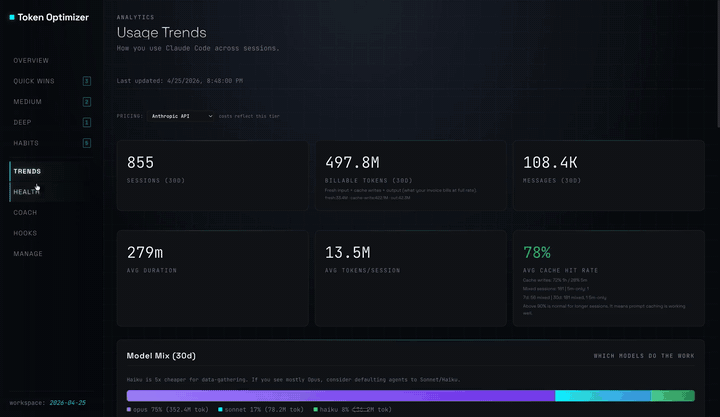

一個 Claude Code 外掛,用靜默 ping 保持閒置工作階段的提示快取溫熱,然後在快取仍然溫熱時壓縮大型工作階段一次。
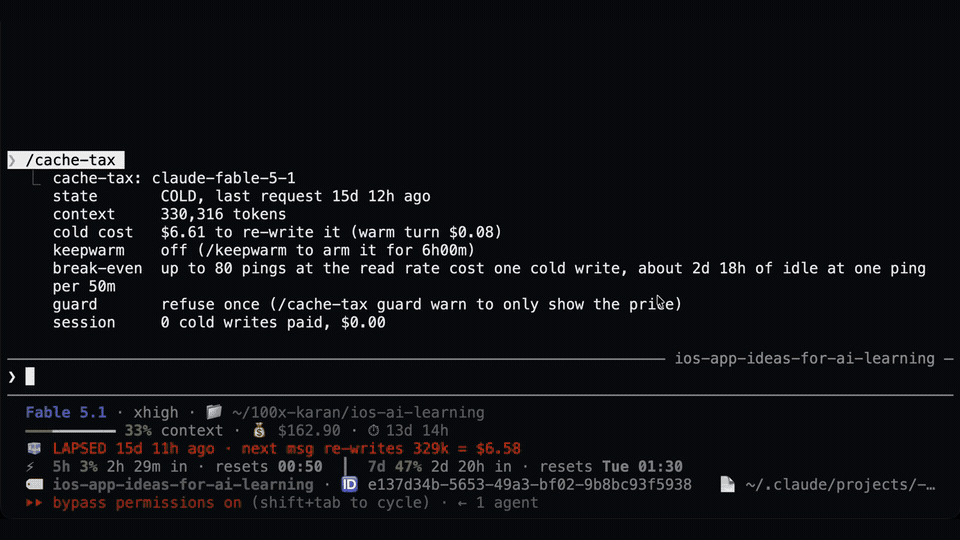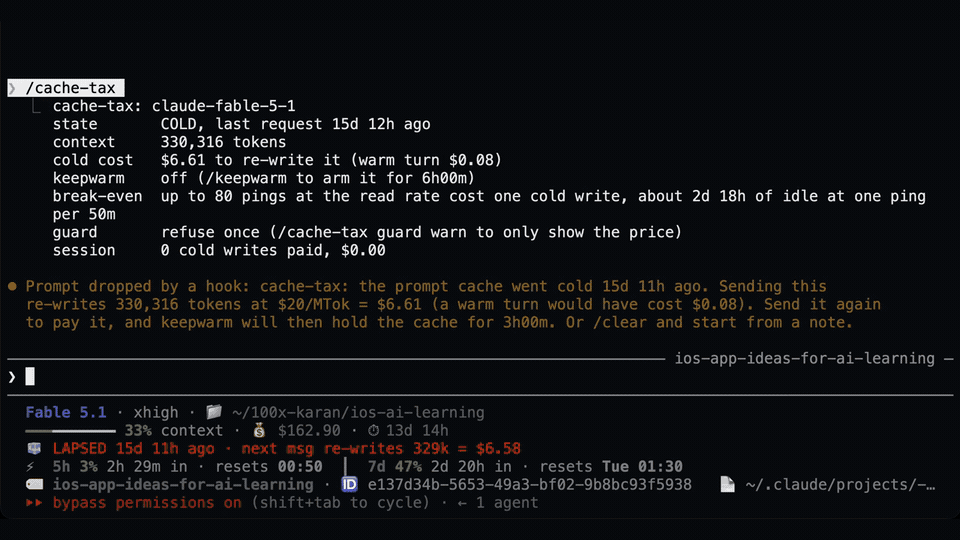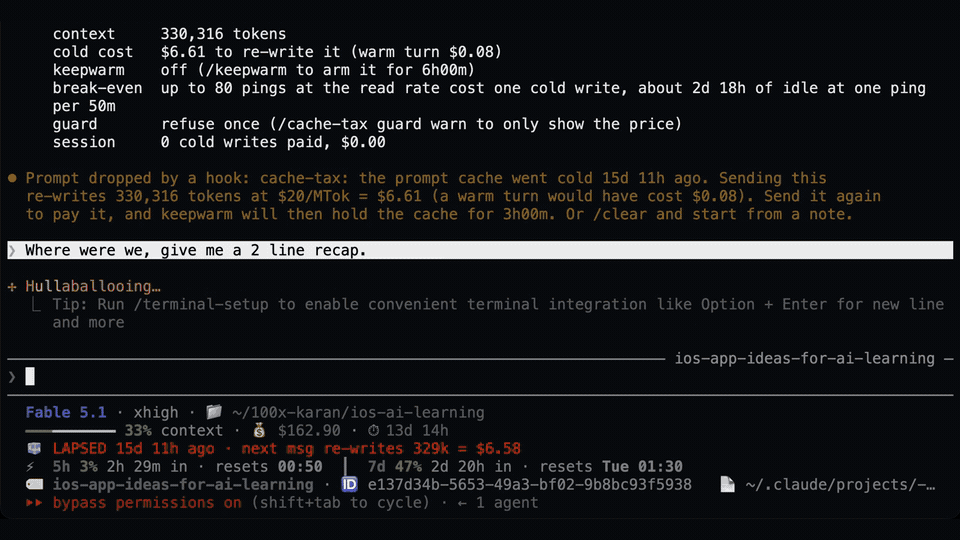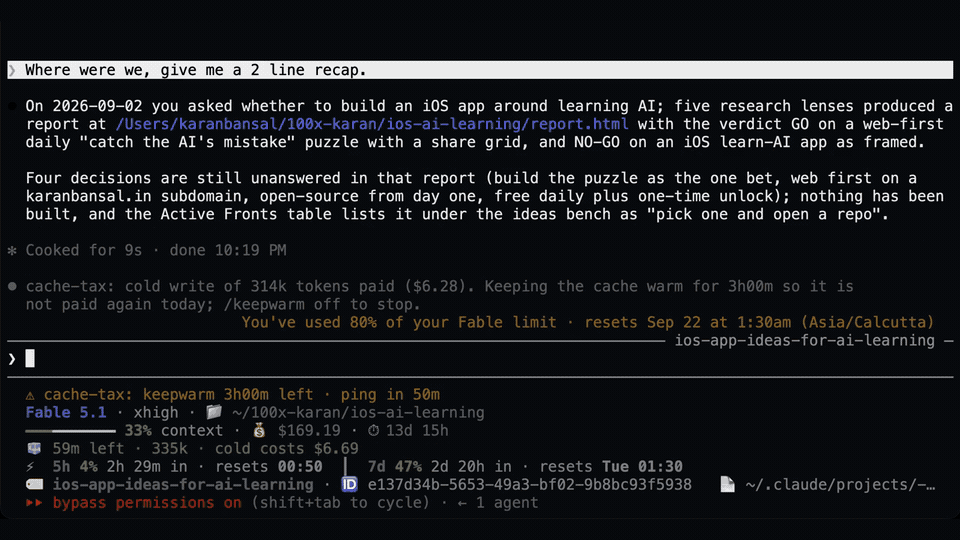
Claude Code 外掛會在休息期間維持一小時提示快取溫熱,並在冷快取送出前顯示一次預估的重寫成本。預熱會使用模型請求並耗用 token。需要 Claude Code 2.1.287+。