
mrd1030@mrd1030
mrd1030/beastlyfactss/tree/main/.claude/mods/zookeeper
編集、shell 呼び出し、チャットで発生する BeastlyFacts のハウスルール違反をその場で指摘し、依頼されない限り npm run build をブロックします。
mrd1030/beastlyfactss/tree/main/.claude/mods/zookeeper
編集、shell 呼び出し、チャットで発生する BeastlyFacts のハウスルール違反をその場で指摘し、依頼されない限り npm run build をブロックします。
まず作者の README で marketplace とプラグイン名を確認してください。コマンドはリポジトリの構成によって変わる場合があります。
claude plugin marketplace add mrd1030/beastlyfactss
claude plugin install zookeeper
BeastlyFacts is a content site with honest, practical, well sourced information about pets and animals, weighted toward reptiles, amphibians, small mammals, and invertebrates. It ships as a prerendered React app on Cloudflare, with every article stored as MDX in this repo.
New session here? Read READMEFIRST.md for current state and what to work on, CLAUDE.md for the working rules, and docs/RULES.md before writing or editing any content. This file is the map of the codebase; those three win over it.
content/, compiled by @mdx-js/rollupsrc/lib/data/ (facts, encyclopedia,
Beastlypedia, guides, affiliate products, legal status)public/_worker.js serving the API routes,
the RSS feeds, and the care package checkout and download endpointsprerender.mjs plus scripts/generate-fact-pages.mjs, so
every article and fact page is static HTML before hydration├── content/ # every article, as MDX
│ ├── guides/ # species guides (cost / handling / health / tank setup / feeding / enrichment)
│ ├── fun-facts/ # numbered list articles
│ ├── blog/ # standalone posts
│ ├── short-story/ # the Chronicles
│ └── CAREPACKAGE Guides/ # printable care package sources and PDFs
├── src/
│ ├── components/
│ │ ├── mdx/ # components usable inside article bodies
│ │ ├── blog/ # article page furniture (Deep Dive, TOC, FAQ)
│ │ ├── beastlypedia/ encyclopedia/ guides/ home/ pack/ legal/
│ │ ├── layout/ shared/ ui/
│ ├── pages/ # route components
│ ├── lib/
│ │ ├── data/ # the content data layer
│ │ ├── generated/ # build output, do not hand edit
│ │ └── seo/ hooks/ utils/
│ └── api/supabaseClient.js
├── scripts/ # content checks and index generators
├── docs/ # rulebook, plans, runbooks, logs
├── supabase/ # SQL schema and edge functions
├── templates/ # MDX starter templates
├── tools/ # image audit, keyword finder, legal research
└── public/ # static assets and _worker.js
npm install
npm run dev
dev regenerates thumbnails and the article, guide, encyclopedia,
Beastlypedia, and legal indexes before starting Vite, so a new MDX file shows
up without extra steps.
Supabase is optional locally. Without VITE_SUPABASE_URL and
VITE_SUPABASE_ANON_KEY, auth and favorites degrade gracefully and everything
else runs.
npm run build runs the full gauntlet before Vite ever starts, so a content
mistake fails the build instead of shipping. Each check also runs on its own:
| Command | What it enforces |
|---|---|
| npm run check:links | every article carries 1 to 2+ in-body internal links, to valid targets |
| npm run check:voice | the voice rules in docs/RULES.md, against scripts/voice-baseline.json |
| npm run check:costs | cost guides cover the required line items |
| npm run check:affiliate | affiliate articles pair affiliate: true with the disclosure |
| npm run check:related | new articles are wired into relatedArticles.js, no dead slugs |
| npm run check:seo | seoTitle and seoDescription length and presence |
| npm run check:images | every referenced image exists and has dimensions |
| npm run check:sources | source URLs in Sources blocks still resolve |
| npm run check:numbers | species numbers stay consistent across guides |
| npm run check:encyclopedia | encyclopedia entries match their guides |
| npm run check:legal-sync | the legal map matches legalStatus.json |
| npm run check:link-depth | internal link depth across the whole site |
npm run lint and npm run typecheck cover the code side.
Content and infographic work stops at the image and internal-link checks. Do
not run npm run build unless you have a reason to.
Start from templates/GUIDE_TEMPLATE.mdx or templates/FUN_FACT_TEMPLATE.mdx
and read templates/README.md for the frontmatter
schema. The frontmatter is the structured data: BlogPosting, BreadcrumbList,
and FAQPage JSON-LD are all generated from it, so never hand write a schema
block in an article.
The non-negotiables, in full in docs/RULES.md:
content/_scheduled-*.Located in src/components/mdx/:
<Figure /> images with captions and alt text<FunFact /> highlighted callouts<KeyTakeaway /> the one thing a reader should leave with<ProsCons /> pros and cons blocks<ComparisonTable /> comparison tables<AffiliateLink /> and <AffiliateDisclosure /> affiliate links and the
disclosure that has to accompany them<Sources /> and <AlsoConsulted /> references<VetDisclaimer /> and <LegalDisclaimer /> for medical and legal content<CarePackageBlock /> care package promo block<MdxLink /> and <DemotedH1 /> internal link and heading handlingThe printable PDF packages sold through Stripe. Sources live in
content/CAREPACKAGE Guides/source/*.html, one self contained HTML file per
package rendered to PDF with headless Chrome. The older care-packages/ folder
is superseded; see its README before touching it. Checkout, the Stripe webhook,
and signed downloads are handled in public/_worker.js.
Built with care for animals and the people who love them.

キャッシュを考慮する /loop worker と CronCreate のバックグラウンド自動化。ruflo ファミリーの繰り返しタスクすべてに使う基盤プラグインです。

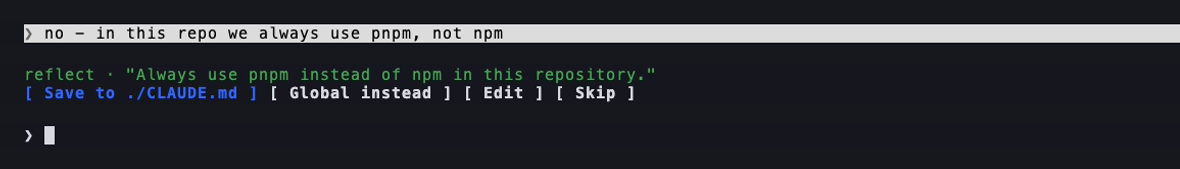
Claude Code mod としての claude-reflect。短いプロンプトごとにモデルチェックを行い、再利用できる修正(任意の言語)を見つけ、プロンプト上のバンドを 1 回押すだけで CLAUDE.md に保存します。

Claude Code 内の初期版 crit。ペインで会話、差分、ファイルにコメントし、レビューを Claude に送り、スレッドで Claude の返答を読めます。