
josippapez@josippapez
josippapez/ai-setup/tree/main/claude/plugins/verified
セッションで確認していないことを確認済みのように主張する回答を Stop/SubagentStop hook でブロックする Claude Code プラグインです。リプレイ・シミュレーターと、主張パターンの変更を出荷前に採点する機能も備えます。
josippapez/ai-setup/tree/main/claude/plugins/verified
Verified は Claude Code プラグインです。Stop と SubagentStop の hooks が、回答の事実に関する主張をセッション中に実際に実行された内容と照合します。パスの主張にはファイルの存在とツール出力、結果の主張には成功した test/build/lint の実行、URL の主張には取得済み URL を使います。裏付けのない主張はターンをモデルに戻します。推測は許容され、引用された範囲は言及として数えられます。3 回ブロックすると、hook は主張を未検証と記録する動作に切り替わります。判定は ~/.claude/verified/ のリプレイ台帳に記録され、固定した実セッション履歴を使って候補の設定変更をオフラインで採点できます(V = catches − false positives − 0.25 × blocked turns)。Dream-RSI の無回帰アプローチに従います。ui.tsx コンポーネントは toast と、フラグが付いた主張を一覧表示するプロンプト上部のバンドを表示します。README には有効/無効な主張クラス、任意の LLM judge、測定比率付きで見送った案、node --test で実行できるテストが記載されています。
まず作者の README で marketplace とプラグイン名を確認してください。コマンドはリポジトリの構成によって変わる場合があります。
claude plugin marketplace add josippapez/ai-setup
claude plugin install verified
A Stop hook that blocks an answer when it claims something the session never checked. The dev-core rules already say "no claim without a file:line, a command output, or a fetched URL". This plugin is the part that enforces it. Before it existed, every correctness mechanism in the repo was advice given before the model acted, and nothing looked at the answer.
It exists for two failures the user reported: answers asserting things nobody checked, and steps skipped mid-task (a "tests pass" with no test run).
The hook reads the session transcript, builds a list of what actually ran, and matches the answer against it. Each claim class is on or off in CONFIG in hooks/claim-patterns.cjs.
| Class | Fires on | Backed by | State |
|---|---|---|---|
| path-missing | a file path | a tool having printed the file's name this session, or the file existing on this machine: from cwd, the git root, the tracked-file list, or the repo of any folder the answer names by ~/ or / path | on |
| command-outcome | "tests pass", "build succeeds", "it works" | a clean test/build/lint run after the last file write | on |
| url | a cited URL | a tool having printed that URL, WebFetch or WebSearch of that host, or an agent-browser, curl or wget command naming it | on |
| path | a file path | a Read/Edit/codegraph of it | off |
| version | v1.2, 1.2.3, "version 4" | find_libs, a manifest read, opensrc | off |
| absence | "there is no X" | a Grep/Glob/rg/codegraph search | off |
Guesses stay legal. The gate checks labelling, not certainty: "I'd use Postgres" passes, and "Postgres handles this natively" blocks unless something was fetched. A span in "double quotes" or after "e.g." counts as a mention, not a claim. A path-missing block asks the model to correct the path, not delete it. After 3 blocks on the same claims, the hook stops blocking and tells the model to mark them unverified.
SubagentStop runs the same checks on subagent answers, against the subagent's own transcript.
~/.claude/verified/, deliberately outside the plugin data dir so a reinstall never wipes it. It holds ledger.jsonl (one node per evaluated turn, with answer text, so it never goes in git), manifests/, worlds.lock.json (the pinned replay history), replay-log.jsonl and offsets.json.
Any change to what gets flagged is scored before it ships. /verified-replay replays a candidate config over the pinned history of real sessions, with no model calls and nothing re-run:
node hooks/replay.cjs --corpus            # current config on the pinned history
node hooks/replay.cjs --corpus --sweep    # every single-knob candidate
node hooks/replay.cjs --candidate <file>  # a forked claim-patterns.cjs vs current
The score is V = catches − false positives − 0.25 × blocked turns (hooks/replay.cjs:91). A change ships only if V doesn't drop. This follows Dream-RSI (dream-rsi.com): the recorded history works as an exact simulator, the scorer (hooks/labels.cjs) stays fixed, and the current config is always one of the candidates. Don't tune labels.cjs to make a favoured config win. Change it only when you've looked at a labelled flag and shown it wrong.
Scores per commit, the scorer's blind spots and the gap to the best possible score are in RESULTS.md.
A fix that only removes wrong blocks can lower V, because the labeller credited those blocks as catches:
On 2026-09-30 the user overrode the rule for three fixes whose removed blocks were all wrong:
| Fix | V with fix vs before |
|---|---|
| Bash agent-browser/curl/wget URLs count as fetched | 371.6 vs 398.1 |
| $param and (group) route folders stay part of a path | 369.8 vs 371.6 |
| A relative path is also looked up in the repos the answer names | 369.3 vs 369.8 |
Overriding again needs the same evidence: every block the fix removes has to be a wrong block. Fixing the labeller so it can see these cases would end the need for overrides.
judge/, off unless VERIFIED_JUDGE_ENABLED=1. Replayed over 476 real turns it fired on 92.5% of them, and each call took 5 to 56 seconds (median about 38) with one call in five failing. The time goes to claude -p starting up, not to the model, so a smaller payload doesn't help. Cost was never the issue at about $0.0017 per turn. Haiku 4.5 got 5 out of 5 on the classification probe, so quality wasn't the problem either.claude -p --bare for the judge. It skips hooks and plugins, but it also breaks login, and the child exits with "Not logged in". The judge uses --settings judge/judge-settings.json plus --strict-mcp-config instead, and VERIFIED_JUDGE=1 stops the child's own Stop hook from recursing.path (was the file read this session). It caught 48 claims over 3260 turns, while blocking 202 the session had already printed. The existence check does the job without those false positives.version. It produced 2 catches out of 67 unresolved flags over 651 turns, the worst ratio of any class. Matching version digits can't tell whether a claim about a release is true.absence. It produced 66 flags over 3260 turns, and no signal ever confirmed one either way.path alongside path-missing. It adds 73 catches but also 179 blocked turns, which scores worse at the 0.25 block weight.command-outcome to a note. It would lose the only class with zero false positives.node hooks/replay.cjs), not only the old-transcript corpus. Since 2026-09-30 a path block there counts as a catch only if the rewrite kept the file.url become a non-blocking note? That would cut the block rate from 18.3% to 16.2%.node --test claude/plugins/verified/hooks/verify-stop.test.cjs
hooks/ui.tsx shows a toast and a band above the prompt listing the flagged claims whenever the Stop hook sends an answer back, since the block reason otherwise reaches only the model. The band clears on the next prompt or on Dismiss.

キャッシュを考慮する /loop worker と CronCreate のバックグラウンド自動化。ruflo ファミリーの繰り返しタスクすべてに使う基盤プラグインです。

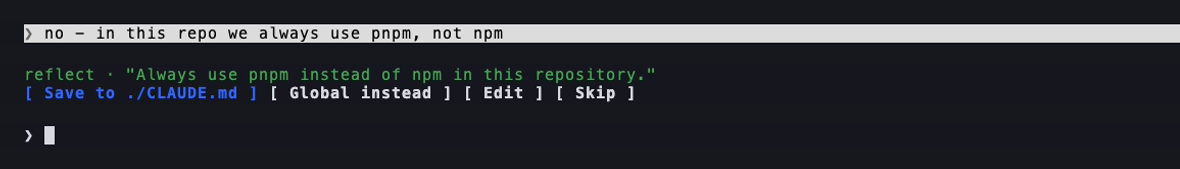
Claude Code mod としての claude-reflect。短いプロンプトごとにモデルチェックを行い、再利用できる修正(任意の言語)を見つけ、プロンプト上のバンドを 1 回押すだけで CLAUDE.md に保存します。

Claude Code 内の初期版 crit。ペインで会話、差分、ファイルにコメントし、レビューを Claude に送り、スレッドで Claude の返答を読めます。